分布式与内存层级
多进程图执行与显式的内存层级核算。两个示例都不需要改动用户 kernel;放置与数据交换都由下层自动推导。
python examples/distributed_halo.pypython examples/hierarchical_memory.pypython examples/paged_giant_graph.pypython examples/auto_offload.pypython examples/paged_cuda.py
CUDA 分页例子先保存图,再以 128 KiB 原生 buffer 预算在 CUDA 上打开,
用 NumPy 独立验证三轮递推前向。高级分页路径使用 tg.Tensor、host staging
及完整驻留输出;不支持 CUDA 分页 backward。参见内存契约。
双进程 halo 交换
它是什么。 Sharding(分片)把一张图切分到多个协作进程上,使
每个进程只拥有一部分节点及其数据。当某个节点的计算需要读取属于
另一个进程的邻居时,该邻居就是一个 halo(ghost)节点,其
值必须跨进程边界复制——这就是 halo 交换。该示例还对整个计算
自动求导:VJP(向量–雅可比积)把标量损失的梯度传播回输入,
无需手写任何反向传播。具体来说,图是一个 8 节点环,节点值为
x[i] = i;每个输出对节点自身及其两个环邻居的值求和。rank 0
拥有节点 0–3,rank 1 拥有节点 4–7,因此 out[3] 和 out[4] 各
需要来自对方 rank 的一个值。
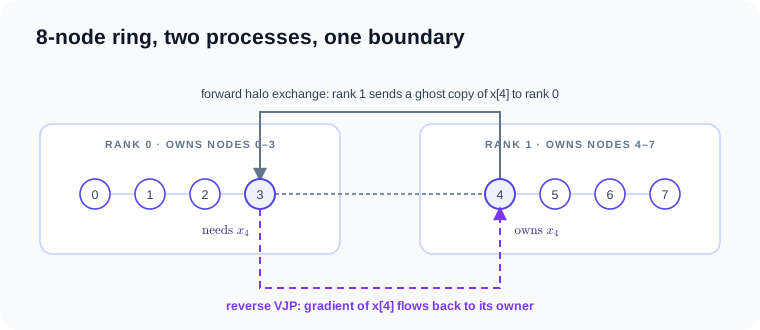
该示例保存一个带版本号的 .gfg,在两个进程上重新打开同一个普通
Graph,只读取各 rank 的目标节点页与边页,然后运行 rank 本地的
Graph.halo() MessagePassing 以及自动 VJP。前向的 owner→ghost
交换和反向的 ghost-cotangent→owner 累加,都由编译器/运行时在
未改动的用户 kernel 之下自动推导。
class NeighborSum(tg.MessagePassing):
    reducer = tg.sum()

    def edge(self, src, dst, edge):
        return src.x


def worker(rank, endpoint, graph_path, queue):
    # The handle is a normal Graph. Only this rank's CSR rows are read from
    # the .gfg PhysicalInstance; topology is not eagerly loaded process-wide.
    graph = tg.load(graph_path).halo(tg.DeviceMesh("cpu", 2), depth=1)
    entities = graph.schema.num_dst
    begin, end = owned_range(entities, 2, rank)
    # Each process owns only its local leading-dimension shard. MessagePassing
    # performs exact halo pack/exchange/unpack below the kernel call.
    local_x = tg.tensor(
        [float(entity) for entity in range(begin, end)], requires_grad=True)
    transport = PipeTransport(rank, 2, {1 - rank: endpoint})
    with DistributedRuntime(transport):
        output = NeighborSum()(graph=graph, src={"x": local_x}, dst={})
        gradient = tg.autograd.grad(output.sum(), local_x)
        values, gradients = output.tolist(), gradient.tolist()
    queue.put((rank, (values, gradients)))
完整源码:examples/distributed_halo.py(可直接运行)
"""Graph.halo automatically executes a rank-local MessagePassing program."""

from __future__ import annotations

import multiprocessing
from pathlib import Path
import tempfile

import tiga as tg
from tiga.distributed import DistributedRuntime, PipeTransport, owned_range


class NeighborSum(tg.MessagePassing):
    reducer = tg.sum()

    def edge(self, src, dst, edge):
        return src.x


def worker(rank, endpoint, graph_path, queue):
    # The handle is a normal Graph. Only this rank's CSR rows are read from
    # the .gfg PhysicalInstance; topology is not eagerly loaded process-wide.
    graph = tg.load(graph_path).halo(tg.DeviceMesh("cpu", 2), depth=1)
    entities = graph.schema.num_dst
    begin, end = owned_range(entities, 2, rank)
    # Each process owns only its local leading-dimension shard. MessagePassing
    # performs exact halo pack/exchange/unpack below the kernel call.
    local_x = tg.tensor(
        [float(entity) for entity in range(begin, end)], requires_grad=True)
    transport = PipeTransport(rank, 2, {1 - rank: endpoint})
    with DistributedRuntime(transport):
        output = NeighborSum()(graph=graph, src={"x": local_x}, dst={})
        gradient = tg.autograd.grad(output.sum(), local_x)
        values, gradients = output.tolist(), gradient.tolist()
    queue.put((rank, (values, gradients)))


# 8-node ring; rank r owns rows [4r, 4r+4). out[i] = x[i-1] + x[i] + x[i+1],
# and every node is read by exactly 3 rows, so the gradient is 3 everywhere —
# including the contributions that cross the rank boundary.
def main():
    entities = 8
    with tempfile.TemporaryDirectory() as directory:
        graph_path = Path(directory) / "ring.gfg"
        tg.save(
            tg.Graph.stencil(
                (entities,), ((-1,), (0,), (1,)), periodic=True),
            graph_path,
        )
        context = multiprocessing.get_context("spawn")
        first, second = context.Pipe(duplex=True)
        queue = context.Queue()
        processes = (
            context.Process(target=worker, args=(0, first, graph_path, queue)),
            context.Process(target=worker, args=(1, second, graph_path, queue)),
        )
        for process in processes:
            process.start()
        shards = dict(queue.get(timeout=10) for _ in processes)
        for process in processes:
            process.join(timeout=10)
            if process.exitcode:
                raise RuntimeError(f"rank exited with code {process.exitcode}")
    return shards

if __name__ == "__main__":
    main()
跨进程与跨机器运行
上面的完整程序验证两个 CPU 进程的前向/VJP,不是多 GPU launcher。
两个 rank 的预期输出分别为 [8,3,6,9]、[12,15,18,13];
源字段梯度均为 [3,3,3,3]。
验证 MPI transport 时,安装 mpi、benchmarks extras 及可用的 MPI launcher,
运行仓库中实际存在的
mpi_halo_exchange.py:
mpiexec -n 2 python -m benchmarks.distributed.mpi_halo_exchange \
  --entities 64 --features 4 --repeats 3 --output output/mpi-sanity/results.json
成功时 JSON 中 correct=true、gate="PASS"。这个命令验证 halo 字节传输,
不是 MessagePassing 梯度。跨机 MPI 还需要 launcher/网络配置、相同环境,
以及各 rank 都能访问的图快照,不能只替换一个 transport 名称便忽略部署条件。
两台机器上的 CUDA 前向/VJP使用完整的双机验证命令。
每台机器启动一个进程,本地设备均可为 cuda:0。TCP 通过主机内存 staging;
NCCL 路径 通过 NCCL 交换
device buffer,同样支持前向/VJP。
TCP 的 host() 与 join() 是不同进程中的阻塞入口,不能在同一个脚本中依次调用。
peer 必须可信(对象消息使用 pickle)、网络互通,并为冷 JIT 留出足够超时。
自动 halo 调度不包括发现机器或启动远程进程。
把张量换出到磁盘
spill() 只改变驻留位置,保留逻辑设备与 autograd 历史;cpu() 是设备拷贝入口。save/load 则读写显式路径的持久化数值快照。预算、共享 view、文件生命周期和 CPU 分页限制见内存与存储。
from pathlib import Path
import tempfile

import tiga as tg

with tempfile.TemporaryDirectory(prefix="tiga-memory-example-") as directory:
    with tg.execution(memory={"host": "1MiB", "nvme": "1MiB"},
                      spill_dir=directory) as run:
        values = tg.tensor([float(i) for i in range(8)], requires_grad=True)
        loss = (values * values).sum()
        loss.spill()  # temporary residency; autograd history survives
        gradients = tg.autograd.grad(loss, values)
        assert gradients.tolist() == [float(2 * i) for i in range(8)]
        back = values.cpu()
        path = Path(directory) / "activations.tiga"
        tg.save(values, path)  # persistent value snapshot, not an eviction
        restored = tg.load(path)  # metadata only until first observation
        assert restored.tolist() == back.tolist()
        print(run.memory_report())
例子验证梯度为 [0, 2, 4, 6, 8, 10, 12, 14],且快照恢复后的数值与原值一致。退出 execution 不会使 Tensor 失效;例子自身的临时目录负责清理演示快照。
磁盘上的超大图
它是什么。 当图本身——而不只是图上的张量——超出 RAM 时,paging
(分页)把拓扑(CSR 邻接结构)留在磁盘上,按有界的目的行页面读取,
prefetch 可让多页同时驻留,并隐藏部分 I/O 延迟,不保证计算永不等待磁盘。
目的行相互独立,因此受支持的分页 reducer 与操作可保持逐行语义。
字段也可以随拓扑一起落盘:
tg.save(graph, path, fields={"src": ..., "edge": ...}) 把它们写成定长
行,tg.load(path).fields("src", requires_grad=True) 返回惰性读取的壳,
此后前向与 tg.autograd.grad 可在受支持的 CPU/原生路径上分页执行。
构图、驻留字段、prefetch 队列和物化输出仍占内存;分页不是进程 RSS 的硬上限。
整个往返在同一个未改动的 kernel 上分三个阶段:
该示例构建一个 1000×1000 的四邻点 stencil(100 万节点,约 400 万条
边),用 tg.save 持久化一次,再用 tg.load 重新打开——只读
manifest,CSR 留在磁盘上——然后以 10 万行为一页、开启 prefetch 执行
一步 Jacobi 平滑,把结果以具名方式换出到磁盘,最后用 tg.from_disk
重新挂载,验证校验和在磁盘 → JIT → 磁盘的往返后保持不变。
在 2000×2000 stencil(400 万节点,约 1600 万条边,NVMe ext4,Ryzen
7 255)上实测(benchmarks/memory_hierarchy/paged_giant_graph.py,
各行校验和完全一致):
| page_rows | prefetch | 页数 | 耗时 | 峰值 RSS |
|---|---|---|---|---|
| 4,000,000(单页) | 关 | 1 | 34.1 s | 3.34 GB |
| 100,000 | 关 | 40 | 37.7 s | 1.08 GB |
| 100,000 | 开 | 40 | 36.6 s | 1.09 GB |
这组存档测量中,100,000 行的页将峰值 RSS 从 3.34 GB 降至约 1.09 GB, 完整调用耗时有所增加。耗时包含页读取与计算;使用目标硬件和页大小运行 benchmark, 可评估这一时间与内存的取舍。
class Smoothing(tg.MessagePassing):
    reducer = tg.sum()

    def edge(self, src, dst, edge):
        del dst, edge
        return src.x  # staged edge item: neighbor value, (E_page,)

    def node(self, dst, aggregate):
        del dst
        return 0.25 * aggregate  # Jacobi average over the 4 neighbors, (N_page,)


def main(grid=(1000, 1000)):
    # Phase 1 — ingest: build the 1000x1000 four-neighbor stencil once and
    # persist it as a versioned .gfg (1M nodes, ~4M edges on NVMe).
    graph_path = Path(tempfile.mkdtemp()) / "giant.gfg"
    tg.save(
        tg.Graph.stencil(grid, ((-1, 0), (1, 0), (0, -1), (0, 1))),
        graph_path,
    )

    # Phase 2 — process: reopen the graph paged (manifest only; the CSR stays
    # on disk) and run the unchanged kernel. The executor streams destination
    # row pages of 100k rows, prefetching page k+1 while page k computes;
    # node/edge fields stay in RAM — only the topology is paged.
    paged = tg.load(graph_path)
    x = tg.tensor([float(node % 977) for node in range(paged.schema.num_dst)])
    started = time.perf_counter()
    out = Smoothing()(graph=paged, src={"x": x}, dst={})  # (1_000_000,)
    elapsed = time.perf_counter() - started

    # Phase 3 — write back: spill the result under a stable name and reattach
    # it the way another process would. The checksum survives the round trip.
    checksum = math.fsum(out.tolist())
    out.disk(name="giant-smoothed")
    reattached = tg.from_disk("giant-smoothed")  # lazy payload, loads on read
    assert math.fsum(reattached.tolist()) == checksum
    print(
        f"paged {paged.schema.num_dst:,} nodes / {paged.num_edges:,} edges "
        f"in {elapsed:.1f}s; checksum {checksum:.0f} round-tripped to disk")
完整源码:examples/paged_giant_graph.py(可直接运行)
"""A disk-resident giant graph: save 1M nodes, stream pages, spill results."""

from __future__ import annotations

import math
import tempfile
import time
from pathlib import Path

import tiga as tg


class Smoothing(tg.MessagePassing):
    reducer = tg.sum()

    def edge(self, src, dst, edge):
        del dst, edge
        return src.x  # staged edge item: neighbor value, (E_page,)

    def node(self, dst, aggregate):
        del dst
        return 0.25 * aggregate  # Jacobi average over the 4 neighbors, (N_page,)


def main(grid=(1000, 1000)):
    # Phase 1 — ingest: build the 1000x1000 four-neighbor stencil once and
    # persist it as a versioned .gfg (1M nodes, ~4M edges on NVMe).
    graph_path = Path(tempfile.mkdtemp()) / "giant.gfg"
    tg.save(
        tg.Graph.stencil(grid, ((-1, 0), (1, 0), (0, -1), (0, 1))),
        graph_path,
    )

    # Phase 2 — process: reopen the graph paged (manifest only; the CSR stays
    # on disk) and run the unchanged kernel. The executor streams destination
    # row pages of 100k rows, prefetching page k+1 while page k computes;
    # node/edge fields stay in RAM — only the topology is paged.
    paged = tg.load(graph_path)
    x = tg.tensor([float(node % 977) for node in range(paged.schema.num_dst)])
    started = time.perf_counter()
    out = Smoothing()(graph=paged, src={"x": x}, dst={})  # (1_000_000,)
    elapsed = time.perf_counter() - started

    # Phase 3 — write back: spill the result under a stable name and reattach
    # it the way another process would. The checksum survives the round trip.
    checksum = math.fsum(out.tolist())
    out.disk(name="giant-smoothed")
    reattached = tg.from_disk("giant-smoothed")  # lazy payload, loads on read
    assert math.fsum(reattached.tolist()) == checksum
    print(
        f"paged {paged.schema.num_dst:,} nodes / {paged.num_edges:,} edges "
        f"in {elapsed:.1f}s; checksum {checksum:.0f} round-tripped to disk")


# Inspect:
#   tg.load(graph_path).explain()            # realization=paged_csr, backing=nvme
#   Smoothing().variants[-1].remarks          # per-page native lowering record
#   TIGA_PAGED_PAGE_ROWS=250000 python examples/paged_giant_graph.py


if __name__ == "__main__":
    main()
RAM 预算下的自动 offload
此阈值在 CSR 构造完成后 才检查,不是外存构图算法,也不限制进程 RSS 或完整工作集。构图、输入字段、prefetch 队列与输出仍须计入实际内存需求。
它是什么。 上面的 tg.save/tg.load 显式往返是为跨进程交接准备的。
每个 CSR 的大小阈值可以自动触发分页:
tg.runtime.auto_offload(ram=...) 生效期间,每个 CSR 构造器
(Graph.from_csr、Graph.stencil、Graph.cat 等)都会检查 CSR 字节
数,超出预算就把拓扑持久化并返回 paged 图——kernel 调用不变,自动按页
流式执行并带 prefetch,全程不需要 tg.save/tg.load:
class Smoothing(tg.MessagePassing):
    reducer = tg.sum()

    def edge(self, src, dst, edge):
        return src.x  # staged edge item: neighbor value, (E_page,)

    def node(self, dst, aggregate):
        return 0.25 * aggregate  # Jacobi average over the 4 neighbors, (N_page,)


def main(grid=(1000, 1000), budget: int = 8 << 20):
    # The 1000x1000 stencil CSR is ~48MB — over the 8MB budget. from_csr
    # persists the topology as .gfg and returns a paged graph instead.
    with tg.runtime.auto_offload(ram=budget):
        graph = tg.Graph.stencil(grid, ((-1, 0), (1, 0), (0, -1), (0, 1)))
        assert graph.schema.realization == "paged_csr"
        x = tg.tensor(                      # (N,) node field — fields stay in RAM
            [float(node % 977) for node in range(graph.schema.num_dst)])
        started = time.perf_counter()
        out = Smoothing()(graph=graph, src={"x": x}, dst={})  # (1_000_000,)
        elapsed = time.perf_counter() - started
完整源码:examples/auto_offload.py(可直接运行)
"""Automatic graph offload: a RAM budget pages a giant graph transparently."""

from __future__ import annotations

import time

import tiga as tg


class Smoothing(tg.MessagePassing):
    reducer = tg.sum()

    def edge(self, src, dst, edge):
        return src.x  # staged edge item: neighbor value, (E_page,)

    def node(self, dst, aggregate):
        return 0.25 * aggregate  # Jacobi average over the 4 neighbors, (N_page,)


def main(grid=(1000, 1000), budget: int = 8 << 20):
    # The 1000x1000 stencil CSR is ~48MB — over the 8MB budget. from_csr
    # persists the topology as .gfg and returns a paged graph instead.
    with tg.runtime.auto_offload(ram=budget):
        graph = tg.Graph.stencil(grid, ((-1, 0), (1, 0), (0, -1), (0, 1)))
        assert graph.schema.realization == "paged_csr"
        x = tg.tensor(                      # (N,) node field — fields stay in RAM
            [float(node % 977) for node in range(graph.schema.num_dst)])
        started = time.perf_counter()
        out = Smoothing()(graph=graph, src={"x": x}, dst={})  # (1_000_000,)
        elapsed = time.perf_counter() - started
    print(
        f"auto-offloaded {graph.schema.num_dst:,} nodes / "
        f"{graph.num_edges:,} edges in {elapsed:.1f}s; "
        f"checksum {sum(out.tolist()):.0f}")


# Inspect:
#   TIGA_GRAPH_RAM_BUDGET=8388608 python examples/auto_offload.py
#   Smoothing()(graph=..., page_rows=50_000, prefetch_depth=4)


if __name__ == "__main__":
    main()
流水线深度——并发预取的页数——默认为 2,可按调用调整
(prefetch_depth=4)或按进程调整
(TIGA_PAGED_PREFETCH_DEPTH);页大小由 page_rows= 或
TIGA_PAGED_PAGE_ROWS 控制。offload 的图落在进程级临时目录、退出
时清理;若需要跨进程存活,设置 TIGA_SPILL_DIR。此路径仅支持 CPU/原生图及受支持的分页操作 图;字段也可经 tg.save(..., fields=...) 落盘,且前向与反向都能
分页执行。
本机编译产物(Ryzen 7 255 · RTX 5070 Ti 实测)
### Smoothing
backend: cpu:0
provider: tiga-runtime
lowering: gf-tensor-relation-autograd
passes: bind-static-csr-snapshot, capture-message-passing-udf, analyze-reducer-algebra, lower-csr-to-gather-segment, fuse-edge-node-regions
remark: [planning] edge/node UDFs remain in the differentiable Tensor DAG
remark: [planning] gf-tensor-vjp generates CSR gather/segment-sum adjoints
remark: [planning] reducer lowering: builtin-additive-state
variant cache: hits=0, misses=10