Distributed and memory hierarchy
Multi-process graph execution and explicit memory-tier accounting. Both examples keep the user kernel unchanged; placement and exchange are derived below it.
python examples/distributed_halo.pypython examples/hierarchical_memory.pypython examples/paged_giant_graph.pypython examples/auto_offload.pypython examples/paged_cuda.py
The CUDA paging example persists a graph, opens it on CUDA under a 128 KiB
native-buffer budget, and checks three recurrent forward steps against NumPy.
The paging path uses tg.Tensor, host staging and a resident output; it does not
implement paged CUDA backward. See the memory contract.
Two-process halo exchange
What it is. Sharding splits a graph across cooperating processes so
that each process owns only a slice of the nodes and their data. When a
node's computation reads a neighbor owned by another process, that neighbor
is a halo (ghost) node whose value must be copied across the process
boundary — the halo exchange. The example also differentiates the
computation: a vector-Jacobian product (VJP) propagates gradients of a
scalar loss back to the inputs with no hand-written backward pass.
Concretely, the graph is an 8-node ring with node values x[i] = i; each
output sums the values of the node itself and its two ring neighbors. Rank 0
owns nodes 0–3, rank 1 owns nodes 4–7, so out[3] and out[4] each need
one value from the other rank.
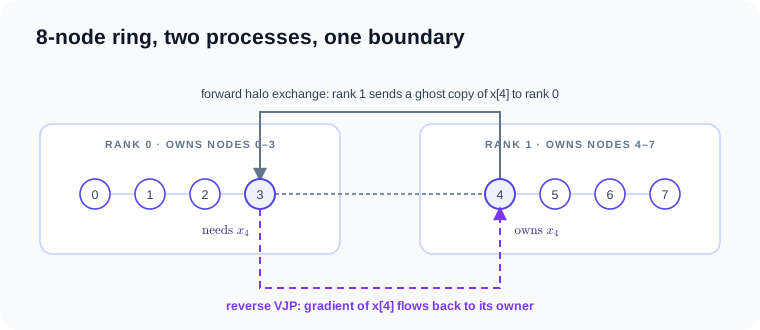
The example saves one versioned .gfg, reopens the same ordinary Graph
on two processes, reads only each rank's destination/edge pages, and runs
rank-local Graph.halo() MessagePassing plus the automatic VJP. The
compiler/runtime derives the forward owner→ghost exchange and the reverse
ghost-cotangent→owner accumulation below the unchanged user kernel.
class NeighborSum(tg.MessagePassing):
    reducer = tg.sum()

    def edge(self, src, dst, edge):
        return src.x


def worker(rank, endpoint, graph_path, queue):
    # The handle is a normal Graph. Only this rank's CSR rows are read from
    # the .gfg PhysicalInstance; topology is not eagerly loaded process-wide.
    graph = tg.load(graph_path).halo(tg.DeviceMesh("cpu", 2), depth=1)
    entities = graph.schema.num_dst
    begin, end = owned_range(entities, 2, rank)
    # Each process owns only its local leading-dimension shard. MessagePassing
    # performs exact halo pack/exchange/unpack below the kernel call.
    local_x = tg.tensor(
        [float(entity) for entity in range(begin, end)], requires_grad=True)
    transport = PipeTransport(rank, 2, {1 - rank: endpoint})
    with DistributedRuntime(transport):
        output = NeighborSum()(graph=graph, src={"x": local_x}, dst={})
        gradient = tg.autograd.grad(output.sum(), local_x)
        values, gradients = output.tolist(), gradient.tolist()
    queue.put((rank, (values, gradients)))
Full source: examples/distributed_halo.py (runs as-is)
"""Graph.halo automatically executes a rank-local MessagePassing program."""

from __future__ import annotations

import multiprocessing
from pathlib import Path
import tempfile

import tiga as tg
from tiga.distributed import DistributedRuntime, PipeTransport, owned_range


class NeighborSum(tg.MessagePassing):
    reducer = tg.sum()

    def edge(self, src, dst, edge):
        return src.x


def worker(rank, endpoint, graph_path, queue):
    # The handle is a normal Graph. Only this rank's CSR rows are read from
    # the .gfg PhysicalInstance; topology is not eagerly loaded process-wide.
    graph = tg.load(graph_path).halo(tg.DeviceMesh("cpu", 2), depth=1)
    entities = graph.schema.num_dst
    begin, end = owned_range(entities, 2, rank)
    # Each process owns only its local leading-dimension shard. MessagePassing
    # performs exact halo pack/exchange/unpack below the kernel call.
    local_x = tg.tensor(
        [float(entity) for entity in range(begin, end)], requires_grad=True)
    transport = PipeTransport(rank, 2, {1 - rank: endpoint})
    with DistributedRuntime(transport):
        output = NeighborSum()(graph=graph, src={"x": local_x}, dst={})
        gradient = tg.autograd.grad(output.sum(), local_x)
        values, gradients = output.tolist(), gradient.tolist()
    queue.put((rank, (values, gradients)))


# 8-node ring; rank r owns rows [4r, 4r+4). out[i] = x[i-1] + x[i] + x[i+1],
# and every node is read by exactly 3 rows, so the gradient is 3 everywhere —
# including the contributions that cross the rank boundary.
def main():
    entities = 8
    with tempfile.TemporaryDirectory() as directory:
        graph_path = Path(directory) / "ring.gfg"
        tg.save(
            tg.Graph.stencil(
                (entities,), ((-1,), (0,), (1,)), periodic=True),
            graph_path,
        )
        context = multiprocessing.get_context("spawn")
        first, second = context.Pipe(duplex=True)
        queue = context.Queue()
        processes = (
            context.Process(target=worker, args=(0, first, graph_path, queue)),
            context.Process(target=worker, args=(1, second, graph_path, queue)),
        )
        for process in processes:
            process.start()
        shards = dict(queue.get(timeout=10) for _ in processes)
        for process in processes:
            process.join(timeout=10)
            if process.exitcode:
                raise RuntimeError(f"rank exited with code {process.exitcode}")
    return shards

if __name__ == "__main__":
    main()
Running across processes and machines
The example above is a complete two-process CPU forward/VJP program, not a
multi-GPU launcher. Expected rank outputs are [8,3,6,9] and [12,15,18,13];
both source gradients are [3,3,3,3].
For an executable MPI transport check, install the mpi and benchmarks
extras plus a working MPI launcher, then run the repository's
mpi_halo_exchange.py:
mpiexec -n 2 python -m benchmarks.distributed.mpi_halo_exchange \
  --entities 64 --features 4 --repeats 3 --output output/mpi-sanity/results.json
Success writes correct=true and gate="PASS". This command checks packed halo
bytes, not MessagePassing gradients. Multi-host MPI additionally needs a configured
launcher/network, matching environments and access to the same graph snapshot.
For two machines with CUDA, use the complete two-host forward/VJP commands.
They start one process per host; both may use local cuda:0.
TCP stages data through host memory. The
NCCL path exchanges device buffers
through NCCL and also supports forward/VJP.
TCP host() and join() are blocking alternatives in different processes,
not consecutive calls in one script. Peers must be trusted (object messages use
pickle), reachable, and configured with a finite timeout that permits cold JIT.
Automatic halo scheduling does not discover hosts or launch remote processes.
Spilling tensors to disk
spill() changes residency while preserving logical device and autograd history; cpu() is a device-copy operation. save/load persist value snapshots at explicit paths. Budget scope, shared views, file lifetime and CPU paging limits are explained in memory and storage.
from pathlib import Path
import tempfile

import tiga as tg

with tempfile.TemporaryDirectory(prefix="tiga-memory-example-") as directory:
    with tg.execution(memory={"host": "1MiB", "nvme": "1MiB"},
                      spill_dir=directory) as run:
        values = tg.tensor([float(i) for i in range(8)], requires_grad=True)
        loss = (values * values).sum()
        loss.spill()  # temporary residency; autograd history survives
        gradients = tg.autograd.grad(loss, values)
        assert gradients.tolist() == [float(2 * i) for i in range(8)]
        back = values.cpu()
        path = Path(directory) / "activations.tiga"
        tg.save(values, path)  # persistent value snapshot, not an eviction
        restored = tg.load(path)  # metadata only until first observation
        assert restored.tolist() == back.tolist()
        print(run.memory_report())
The example verifies the gradient [0, 2, 4, 6, 8, 10, 12, 14] and exact snapshot values. Leaving execution does not invalidate a Tensor; the example's own temporary directory cleans up its demonstration snapshot.
A disk-resident giant graph
What it is. When the graph itself — not just the tensors on it — exceeds
RAM, paging keeps the topology (the CSR adjacency) on disk and reads it in
bounded destination-row pages. Prefetch may keep multiple pages resident and
can hide some I/O latency; it does not guarantee that computation never waits
on storage. Destination-row independence preserves per-row semantics for the
supported paged reducers and operations. Fields can join the topology on
disk: tg.save(graph, path, fields={"src": ..., "edge": ...}) persists them
as fixed-width rows, tg.load(path).fields("src", requires_grad=True)
returns lazily-read shells, and both the forward pass and
tg.autograd.grad then run paged on supported CPU/native paths. Construction,
resident fields, prefetched pages and a materialized output can still consume
RAM; paging is not a hard process-RSS limit.
The round trip is three phases on one unchanged kernel:
The example builds a 1000×1000 four-neighbor stencil (1M nodes, ~4M edges),
persists it once with tg.save, reopens it with tg.load — which reads only
the manifest, leaving the CSR on disk — runs one Jacobi smoothing step over
100k-row pages with prefetch on, spills the result under a stable name, and
reattaches it with tg.from_disk to verify the checksum survives the
disk → JIT → disk round trip.
Measured on a 2000×2000 stencil (4M nodes, ~16M edges, NVMe ext4, Ryzen
7 255) with benchmarks/memory_hierarchy/paged_giant_graph.py — identical
checksum in every row:
| page_rows | prefetch | pages | elapsed | peak RSS |
|---|---|---|---|---|
| 4,000,000 (one page) | off | 1 | 34.1 s | 3.34 GB |
| 100,000 | off | 40 | 37.7 s | 1.08 GB |
| 100,000 | on | 40 | 36.6 s | 1.09 GB |
In these archived measurements, 100,000-row pages reduce peak RSS from 3.34 GB to about 1.09 GB, with a longer completed-call time. The elapsed time includes page loading and computation. Use the benchmark with the intended hardware and page size to evaluate this tradeoff.
class Smoothing(tg.MessagePassing):
    reducer = tg.sum()

    def edge(self, src, dst, edge):
        del dst, edge
        return src.x  # staged edge item: neighbor value, (E_page,)

    def node(self, dst, aggregate):
        del dst
        return 0.25 * aggregate  # Jacobi average over the 4 neighbors, (N_page,)


def main(grid=(1000, 1000)):
    # Phase 1 — ingest: build the 1000x1000 four-neighbor stencil once and
    # persist it as a versioned .gfg (1M nodes, ~4M edges on NVMe).
    graph_path = Path(tempfile.mkdtemp()) / "giant.gfg"
    tg.save(
        tg.Graph.stencil(grid, ((-1, 0), (1, 0), (0, -1), (0, 1))),
        graph_path,
    )

    # Phase 2 — process: reopen the graph paged (manifest only; the CSR stays
    # on disk) and run the unchanged kernel. The executor streams destination
    # row pages of 100k rows, prefetching page k+1 while page k computes;
    # node/edge fields stay in RAM — only the topology is paged.
    paged = tg.load(graph_path)
    x = tg.tensor([float(node % 977) for node in range(paged.schema.num_dst)])
    started = time.perf_counter()
    out = Smoothing()(graph=paged, src={"x": x}, dst={})  # (1_000_000,)
    elapsed = time.perf_counter() - started

    # Phase 3 — write back: spill the result under a stable name and reattach
    # it the way another process would. The checksum survives the round trip.
    checksum = math.fsum(out.tolist())
    out.disk(name="giant-smoothed")
    reattached = tg.from_disk("giant-smoothed")  # lazy payload, loads on read
    assert math.fsum(reattached.tolist()) == checksum
    print(
        f"paged {paged.schema.num_dst:,} nodes / {paged.num_edges:,} edges "
        f"in {elapsed:.1f}s; checksum {checksum:.0f} round-tripped to disk")
Full source: examples/paged_giant_graph.py (runs as-is)
"""A disk-resident giant graph: save 1M nodes, stream pages, spill results."""

from __future__ import annotations

import math
import tempfile
import time
from pathlib import Path

import tiga as tg


class Smoothing(tg.MessagePassing):
    reducer = tg.sum()

    def edge(self, src, dst, edge):
        del dst, edge
        return src.x  # staged edge item: neighbor value, (E_page,)

    def node(self, dst, aggregate):
        del dst
        return 0.25 * aggregate  # Jacobi average over the 4 neighbors, (N_page,)


def main(grid=(1000, 1000)):
    # Phase 1 — ingest: build the 1000x1000 four-neighbor stencil once and
    # persist it as a versioned .gfg (1M nodes, ~4M edges on NVMe).
    graph_path = Path(tempfile.mkdtemp()) / "giant.gfg"
    tg.save(
        tg.Graph.stencil(grid, ((-1, 0), (1, 0), (0, -1), (0, 1))),
        graph_path,
    )

    # Phase 2 — process: reopen the graph paged (manifest only; the CSR stays
    # on disk) and run the unchanged kernel. The executor streams destination
    # row pages of 100k rows, prefetching page k+1 while page k computes;
    # node/edge fields stay in RAM — only the topology is paged.
    paged = tg.load(graph_path)
    x = tg.tensor([float(node % 977) for node in range(paged.schema.num_dst)])
    started = time.perf_counter()
    out = Smoothing()(graph=paged, src={"x": x}, dst={})  # (1_000_000,)
    elapsed = time.perf_counter() - started

    # Phase 3 — write back: spill the result under a stable name and reattach
    # it the way another process would. The checksum survives the round trip.
    checksum = math.fsum(out.tolist())
    out.disk(name="giant-smoothed")
    reattached = tg.from_disk("giant-smoothed")  # lazy payload, loads on read
    assert math.fsum(reattached.tolist()) == checksum
    print(
        f"paged {paged.schema.num_dst:,} nodes / {paged.num_edges:,} edges "
        f"in {elapsed:.1f}s; checksum {checksum:.0f} round-tripped to disk")


# Inspect:
#   tg.load(graph_path).explain()            # realization=paged_csr, backing=nvme
#   Smoothing().variants[-1].remarks          # per-page native lowering record
#   TIGA_PAGED_PAGE_ROWS=250000 python examples/paged_giant_graph.py


if __name__ == "__main__":
    main()
Automatic offload under a RAM budget
What it is. The explicit tg.save/tg.load dance above exists for
cross-process handoff. A per-CSR threshold can make the paging decision automatically: while
tg.runtime.auto_offload(ram=...) is active, every CSR builder
(Graph.from_csr, Graph.stencil, Graph.cat, ...) checks the CSR byte
size and, over budget, persists the topology and returns a paged graph —
the unchanged native kernel call then streams pages with prefetch.
The threshold is checked after CSR construction; it is not an out-of-core
builder or a total-RSS/working-set budget:
class Smoothing(tg.MessagePassing):
    reducer = tg.sum()

    def edge(self, src, dst, edge):
        return src.x  # staged edge item: neighbor value, (E_page,)

    def node(self, dst, aggregate):
        return 0.25 * aggregate  # Jacobi average over the 4 neighbors, (N_page,)


def main(grid=(1000, 1000), budget: int = 8 << 20):
    # The 1000x1000 stencil CSR is ~48MB — over the 8MB budget. from_csr
    # persists the topology as .gfg and returns a paged graph instead.
    with tg.runtime.auto_offload(ram=budget):
        graph = tg.Graph.stencil(grid, ((-1, 0), (1, 0), (0, -1), (0, 1)))
        assert graph.schema.realization == "paged_csr"
        x = tg.tensor(                      # (N,) node field — fields stay in RAM
            [float(node % 977) for node in range(graph.schema.num_dst)])
        started = time.perf_counter()
        out = Smoothing()(graph=graph, src={"x": x}, dst={})  # (1_000_000,)
        elapsed = time.perf_counter() - started
Full source: examples/auto_offload.py (runs as-is)
"""Automatic graph offload: a RAM budget pages a giant graph transparently."""

from __future__ import annotations

import time

import tiga as tg


class Smoothing(tg.MessagePassing):
    reducer = tg.sum()

    def edge(self, src, dst, edge):
        return src.x  # staged edge item: neighbor value, (E_page,)

    def node(self, dst, aggregate):
        return 0.25 * aggregate  # Jacobi average over the 4 neighbors, (N_page,)


def main(grid=(1000, 1000), budget: int = 8 << 20):
    # The 1000x1000 stencil CSR is ~48MB — over the 8MB budget. from_csr
    # persists the topology as .gfg and returns a paged graph instead.
    with tg.runtime.auto_offload(ram=budget):
        graph = tg.Graph.stencil(grid, ((-1, 0), (1, 0), (0, -1), (0, 1)))
        assert graph.schema.realization == "paged_csr"
        x = tg.tensor(                      # (N,) node field — fields stay in RAM
            [float(node % 977) for node in range(graph.schema.num_dst)])
        started = time.perf_counter()
        out = Smoothing()(graph=graph, src={"x": x}, dst={})  # (1_000_000,)
        elapsed = time.perf_counter() - started
    print(
        f"auto-offloaded {graph.schema.num_dst:,} nodes / "
        f"{graph.num_edges:,} edges in {elapsed:.1f}s; "
        f"checksum {sum(out.tolist()):.0f}")


# Inspect:
#   TIGA_GRAPH_RAM_BUDGET=8388608 python examples/auto_offload.py
#   Smoothing()(graph=..., page_rows=50_000, prefetch_depth=4)


if __name__ == "__main__":
    main()
The pipeline depth — pages read ahead concurrently — defaults to 2 and is
tunable per call (prefetch_depth=4) or process-wide
(TIGA_PAGED_PREFETCH_DEPTH); page size follows page_rows= or
TIGA_PAGED_PAGE_ROWS. Offloaded graphs land in a per-process
directory cleaned up at exit, or under TIGA_SPILL_DIR when the
graph should outlive the process. This path requires CPU/native graphs and supported paged operations;
fields can be offloaded too via tg.save(..., fields=...), and both forward
and backward run paged.
Measured compilation artifacts (Ryzen 7 255 · RTX 5070 Ti)
### Smoothing
backend: cpu:0
provider: tiga-runtime
lowering: gf-tensor-relation-autograd
passes: bind-static-csr-snapshot, capture-message-passing-udf, analyze-reducer-algebra, lower-csr-to-gather-segment, fuse-edge-node-regions
remark: [planning] edge/node UDFs remain in the differentiable Tensor DAG
remark: [planning] gf-tensor-vjp generates CSR gather/segment-sum adjoints
remark: [planning] reducer lowering: builtin-additive-state
variant cache: hits=0, misses=10