Benchmark results
For runtime/memory comparisons, large-graph capacity and distributed overhead, see performance and scalability. This page contains the historical archive.
These are historical measurements, not performance results for the current checkout. The archived input set covers 44 registered cases across 18 operations, plus six supporting artifacts. GPU cases use the recorded RTX 5070 Ti environment; CPU results belong to the paired host. No cross-device score is computed.
Reproduce the charts · Download raw evidence · Chart-to-input index · Full matrix
Scope and provenance
Original code revisions, driver/package versions and raw repetitions are incomplete in some historical files. Replotting is reproducible from the archive; equivalent fresh performance is not guaranteed. A --quick run is a smoke measurement, not a reproduction of every archived case.
Reading the figures
Fresh large-graph capacity evidence is reported separately in the billion-edge experiment. Its complete forward timings must not be mixed with the historical warm operator timings below.
A speedup above 1 means the named candidate is faster than its stated peer; milliseconds remain visible. Ratios from different workloads or timing scopes are never averaged. F means feature width, not floating-point precision. Memory charts distinguish estimated per-edge intermediates from measured peak allocation. Scroll charts horizontally on narrow screens; click a figure to open its SVG at full size.
GPU
Weighted CSR aggregation computes a weighted sum over each destination row. The selected topology slices use 131,072 rows and mean degree 16, FP32 values, and the index width encoded by each archived case. F=1/16/64 is the feature width.
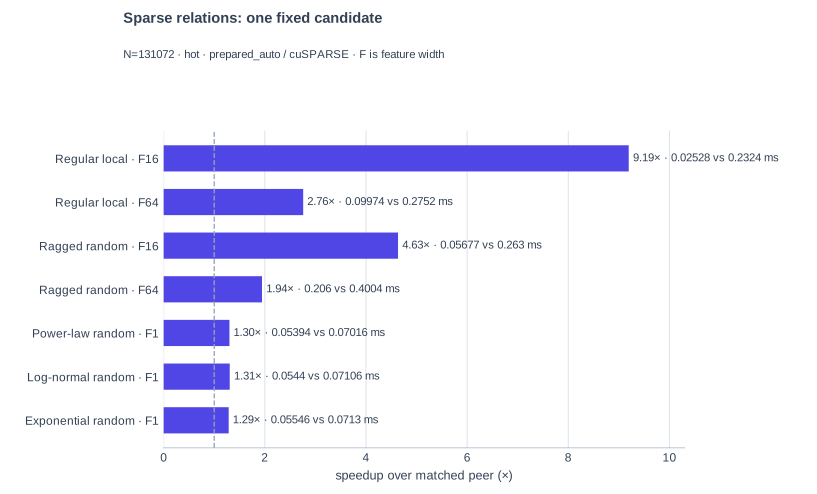
The candidate is tiga.prepared_auto, the peer is torch.sparse.mm, and cache is hot. Preparation is outside this warm timing. This is a fixed selection, not a claim of winning every registered topology. All sparse cases.
An edge MLP consumes relative position and source features, followed by destination aggregation. The fused and eager paths compute the same selected workload; a handwritten Triton tile is an oracle, not compiler-generated code.
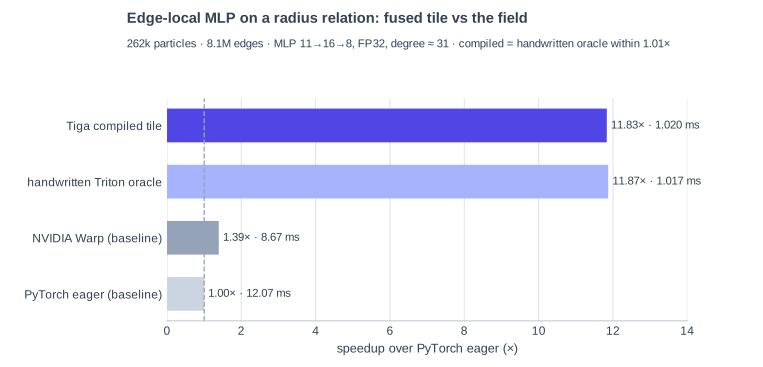
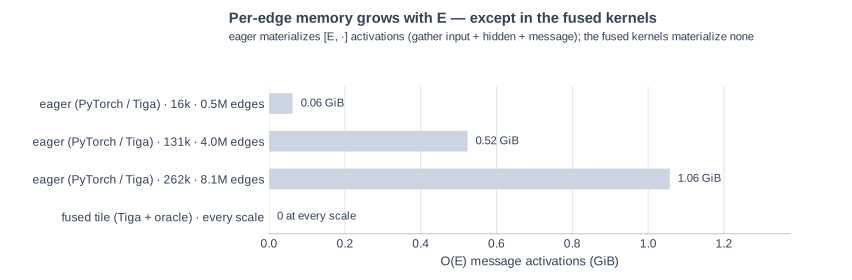
Zero in the second chart means no materialized per-edge activation array, not zero total device memory. Its GiB values are derived from intermediate tensor sizes; they are not peak-allocator measurements.
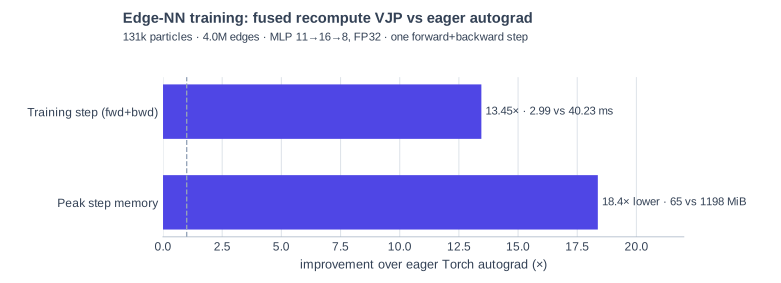
The training chart compares a forward+backward step and measured peak allocation; its timing scope differs from forward-only. Forward case · Backward case · Program examples.
This graph attention case includes an edge-wise score, destination normalization and aggregation. It is not dense SDPA.
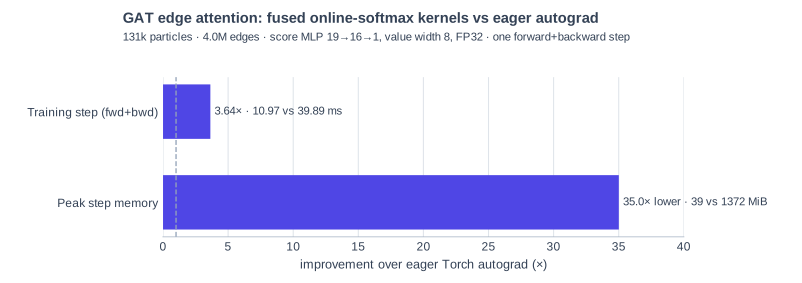
The peer is eager autograd on the same recorded graph. This supporting case is archived but not registered in the 44-case matrix; its exact source is in the chart index.
Dense exact attention, linear attention and tile-pruned sparse attention are different mathematical workloads. Each row has its own matched peer; comparisons across rows are not rankings.
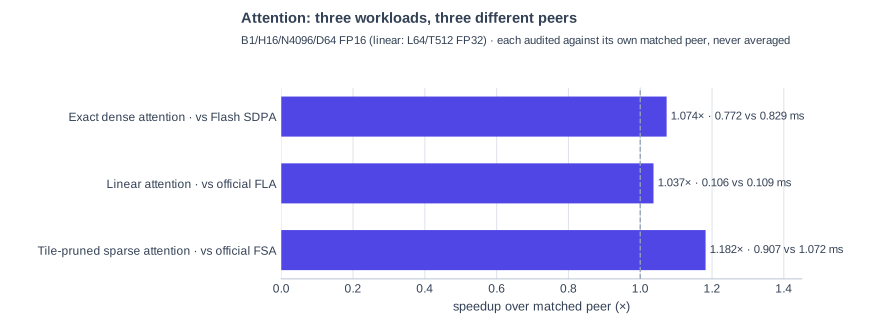
Dense cases · Linear case · Sparse case. The matrix states shapes, precision and provider identity.
Building a radius topology, consuming a ready topology, and rebuilding then consuming have different timing boundaries. Reuse excludes construction; end-to-end includes it.
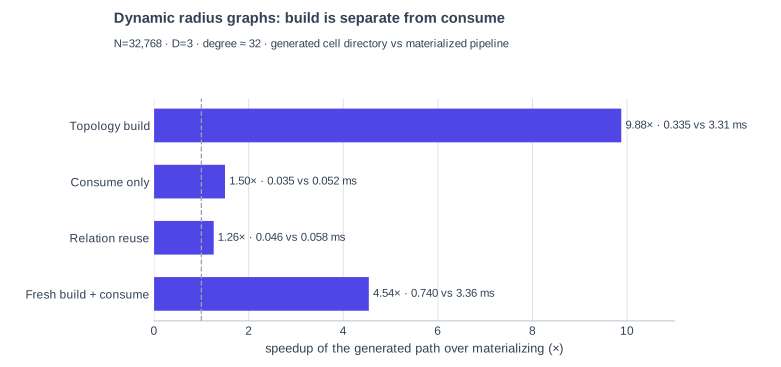
No phase-only ratio establishes the end-to-end speedup. Build case · Consumption case.
Across the compiler
Each row below selects an explicit archived workload and a matched baseline. The selections are fixed by the generator, not an automatic best-case scan.
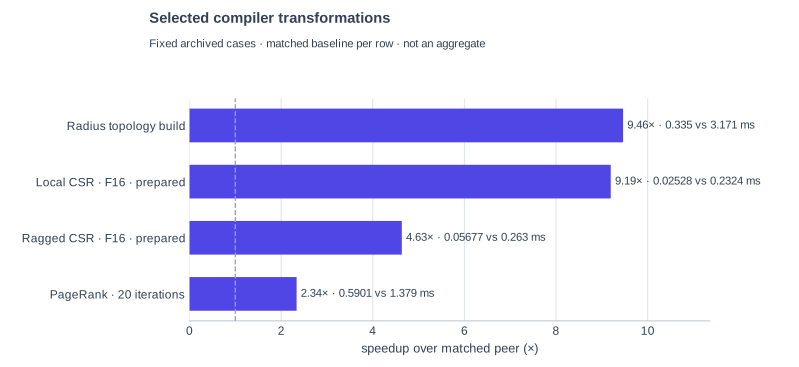
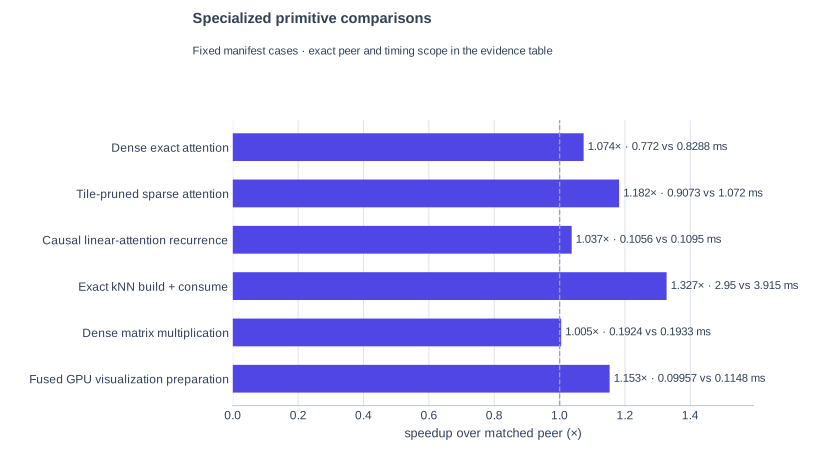
Baseline names and exact filters are in benchmarks/evidence_manifest.json and benchmarks/common/plot_docs_results.py; absolute candidate/peer times are printed beside the bars. PageRank · kNN · Matmul calibration · Heatmap.
CPU
The same FP32/i32 degree-16 relation loop is compared with SciPy CSR matvec and Torch sparse at two node counts, with 16 threads. Both wins and losses are shown.
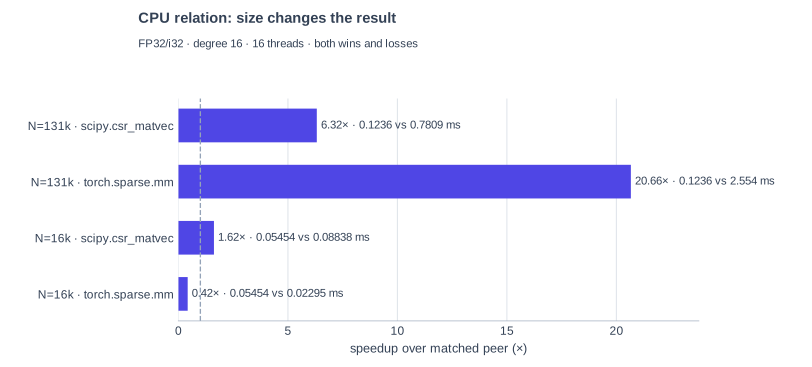
The 131k case is registered; the 16k comparison is a supporting archive. The result does not establish scaling across CPUs, thread counts or NUMA placements. Registered CPU relation.
Historical internal overlap probe, not the public execution policy (which completes communication before computation). Two CPU processes use a deliberately delayed transport link; this is not an NVLink, RDMA or multi-GPU benchmark.
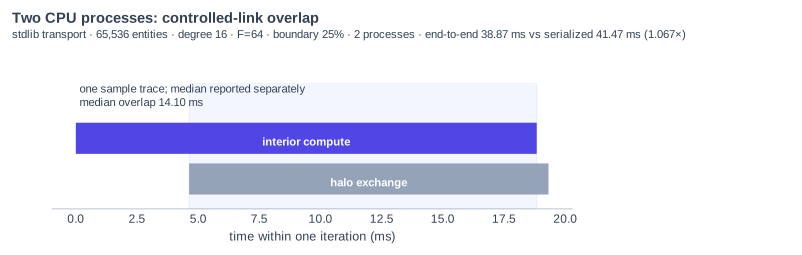
The timeline is one rank's first sample; the median annotation comes from the full recorded sample set. It does not claim that every sample has the same overlap. Runnable distributed example.
The full matrix
The table is generated from the same archived registered inputs, including slower paths. It is the detailed evidence view, not another independent measurement. Each operation lists its case conditions, timing scope and peer.
Weighted neighbor sum
Each node sums its neighbors' values multiplied by edge weights. The summary fixes the comparison to tiga.prepared_auto versus torch.sparse.mm with hot data caches, retaining every registered topology and feature width rather than selecting the largest speedup.
All rows use 131,072 nodes and FP32 values. F is the number of values per node; i32/i64 describe integer indices, not value precision. Lower latency is better; speedup is peer time / Tiga time, so below 1 is slower.
| Topology | Neighbors | Index | F | Tiga (ms) | Torch sparse (ms) | Speedup |
|---|---|---|---|---|---|---|
| regular | local | i64 | 1 | 0.020 | 0.047 | 2.31× |
| regular | local | i64 | 16 | 0.025 | 0.232 | 9.19× |
| regular | local | i64 | 64 | 0.100 | 0.275 | 2.76× |
| irregular | random | i32 | 16 | 0.057 | 0.263 | 4.63× |
| irregular | random | i32 | 64 | 0.206 | 0.400 | 1.94× |
| powerlaw | local | i32 | 1 | 0.020 | 0.041 | 2.00× |
| powerlaw | local | i64 | 1 | 0.023 | 0.038 | 1.65× |
| powerlaw | random | i32 | 1 | 0.054 | 0.070 | 1.30× |
| powerlaw | random | i64 | 1 | 0.054 | 0.071 | 1.32× |
| lognormal | random | i32 | 1 | 0.054 | 0.071 | 1.31× |
| exponential | random | i32 | 1 | 0.055 | 0.071 | 1.29× |
Regular graphs have equal neighbor counts; the other distributions test uneven work. Local/random refer to source-index locality, not network communication.
prepared_auto excludes binding/preparation, initial compilation and graph construction. Hot reuses data; cold perturbs the data cache before timing, not first-time JIT compilation. These historical paths do not establish end-to-end performance of today's ordinary Torch calls.
All providers and hot/cold results remain below. Confidence intervals express sampling uncertainty; passing a performance check is not a correctness or release certification.
All measurements and implementation details
| Case | Bucket | Candidate (ms) | Baseline (ms) | Speedup | 95% CI | Gate |
|---|---|---|---|---|---|---|
powerlaw_local_cuda_i32_n131072_degree16_f1 |
powerlaw · local · hot · F1 · N131072 | tiga.compiler_chunked_tail 0.027 |
torch.sparse.mm 0.041 |
1.51× | [1.39, 1.71] | pass |
powerlaw_local_cuda_i32_n131072_degree16_f1 |
powerlaw · local · hot · F1 · N131072 | tiga.prepared_auto 0.020 |
torch.sparse.mm 0.041 |
2.00× | [1.89, 2.30] | pass |
powerlaw_local_cuda_i32_n131072_degree16_f1 |
powerlaw · local · cold · F1 · N131072 | tiga.compiler_chunked_tail 0.051 |
torch.sparse.mm 0.071 |
1.39× | [1.36, 1.50] | pass |
powerlaw_local_cuda_i32_n131072_degree16_f1 |
powerlaw · local · cold · F1 · N131072 | tiga.prepared_auto 0.051 |
torch.sparse.mm 0.071 |
1.40× | [1.35, 1.51] | pass |
powerlaw_local_cuda_i64_n131072_degree16_f1 |
powerlaw · local · hot · F1 | tiga.prepared_auto 0.023 |
torch.sparse.mm 0.038 |
1.65× | [1.63, 1.72] | pass |
powerlaw_local_cuda_i64_n131072_degree16_f1 |
powerlaw · local · cold · F1 | tiga.prepared_auto 0.061 |
torch.sparse.mm 0.082 |
1.33× | [1.30, 1.44] | pass |
powerlaw_random_cuda_i32_n131072_degree16_f1 |
powerlaw · random · hot · F1 · N131072 | tiga.compiler_chunked_tail 0.054 |
torch.sparse.mm 0.070 |
1.31× | [1.28, 1.33] | pass |
powerlaw_random_cuda_i32_n131072_degree16_f1 |
powerlaw · random · hot · F1 · N131072 | tiga.prepared_auto 0.054 |
torch.sparse.mm 0.070 |
1.30× | [1.27, 1.32] | pass |
powerlaw_random_cuda_i32_n131072_degree16_f1 |
powerlaw · random · cold · F1 · N131072 | tiga.compiler_chunked_tail 0.059 |
torch.sparse.mm 0.086 |
1.46× | [1.45, 1.49] | pass |
powerlaw_random_cuda_i32_n131072_degree16_f1 |
powerlaw · random · cold · F1 · N131072 | tiga.prepared_auto 0.059 |
torch.sparse.mm 0.086 |
1.45× | [1.42, 1.47] | pass |
powerlaw_random_cuda_i64_n131072_degree16_f1 |
powerlaw · random · hot · F1 | tiga.prepared_auto 0.054 |
torch.sparse.mm 0.071 |
1.32× | [1.28, 1.35] | pass |
powerlaw_random_cuda_i64_n131072_degree16_f1 |
powerlaw · random · cold · F1 | tiga.prepared_auto 0.079 |
torch.sparse.mm 0.095 |
1.20× | [1.19, 1.21] | pass |
lognormal_random_cuda_i32_n131072_degree16_f1 |
lognormal · random · hot · F1 · N131072 | tiga.compiler_chunked_tail 0.059 |
torch.sparse.mm 0.071 |
1.20× | [1.17, 1.23] | pass |
lognormal_random_cuda_i32_n131072_degree16_f1 |
lognormal · random · hot · F1 · N131072 | tiga.prepared_auto 0.054 |
torch.sparse.mm 0.071 |
1.31× | [1.26, 1.34] | pass |
lognormal_random_cuda_i32_n131072_degree16_f1 |
lognormal · random · cold · F1 · N131072 | tiga.compiler_chunked_tail 0.076 |
torch.sparse.mm 0.086 |
1.12× | [1.11, 1.13] | pass |
lognormal_random_cuda_i32_n131072_degree16_f1 |
lognormal · random · cold · F1 · N131072 | tiga.prepared_auto 0.070 |
torch.sparse.mm 0.086 |
1.22× | [1.20, 1.23] | pass |
exponential_random_cuda_i32_n131072_degree16_f1 |
exponential · random · hot · F1 · N131072 | tiga.compiler_chunked_tail 0.059 |
torch.sparse.mm 0.071 |
1.20× | [1.18, 1.23] | pass |
exponential_random_cuda_i32_n131072_degree16_f1 |
exponential · random · hot · F1 · N131072 | tiga.prepared_auto 0.055 |
torch.sparse.mm 0.071 |
1.29× | [1.26, 1.31] | pass |
exponential_random_cuda_i32_n131072_degree16_f1 |
exponential · random · cold · F1 · N131072 | tiga.compiler_chunked_tail 0.075 |
torch.sparse.mm 0.087 |
1.15× | [1.14, 1.17] | pass |
exponential_random_cuda_i32_n131072_degree16_f1 |
exponential · random · cold · F1 · N131072 | tiga.prepared_auto 0.071 |
torch.sparse.mm 0.087 |
1.23× | [1.21, 1.25] | pass |
No registered gates for the case below — rows are the measured providers. Ratios use the predeclared peer where available, otherwise the fastest non-Tiga peer with matching conditions.
| Case | Bucket | Provider | Median (ms) | Peer | Speedup vs peer |
|---|---|---|---|---|---|
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.prepared_auto |
0.020 | torch.sparse.mm |
2.31× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.auto |
0.046 | torch.sparse.mm |
1.03× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.reference |
0.216 | torch.sparse.mm |
0.22× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.sparse.mm |
0.047 | torch.sparse.mm |
1.00× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.compile.index_add |
0.083 | torch.sparse.mm |
0.57× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.index_add |
0.084 | torch.sparse.mm |
0.56× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | triton.csr |
0.379 | torch.sparse.mm |
0.12× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.prepared_auto |
0.025 | torch.sparse.mm |
9.19× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.auto |
0.062 | torch.sparse.mm |
3.77× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.reference |
3.115 | torch.sparse.mm |
0.07× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.sparse.mm |
0.232 | torch.sparse.mm |
1.00× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.compile.index_add |
0.234 | torch.sparse.mm |
0.99× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | triton.csr |
0.427 | torch.sparse.mm |
0.54× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | pyg.message_passing |
1.748 | torch.sparse.mm |
0.13× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.index_add |
1.832 | torch.sparse.mm |
0.13× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.auto |
0.095 | torch.sparse.mm |
2.89× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.prepared_auto |
0.100 | torch.sparse.mm |
2.76× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.reference |
5.621 | torch.sparse.mm |
0.05× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.sparse.mm |
0.275 | torch.sparse.mm |
1.00× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | triton.csr |
0.453 | torch.sparse.mm |
0.61× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.compile.index_add |
0.577 | torch.sparse.mm |
0.48× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | pyg.message_passing |
3.561 | torch.sparse.mm |
0.08× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.index_add |
4.188 | torch.sparse.mm |
0.07× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.prepared_auto |
0.046 | torch.sparse.mm |
1.72× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.auto |
0.055 | torch.sparse.mm |
1.43× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.reference |
0.216 | torch.sparse.mm |
0.36× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.sparse.mm |
0.079 | torch.sparse.mm |
1.00× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.index_add |
0.113 | torch.sparse.mm |
0.70× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.compile.index_add |
0.115 | torch.sparse.mm |
0.68× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | triton.csr |
0.387 | torch.sparse.mm |
0.20× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.prepared_auto |
0.058 | torch.compile.index_add |
3.40× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.auto |
0.067 | torch.compile.index_add |
2.95× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.reference |
3.098 | torch.compile.index_add |
0.06× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.compile.index_add |
0.197 | torch.compile.index_add |
1.00× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.sparse.mm |
0.233 | torch.compile.index_add |
0.84× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | triton.csr |
0.449 | torch.compile.index_add |
0.44× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | pyg.message_passing |
1.748 | torch.compile.index_add |
0.11× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.index_add |
1.841 | torch.compile.index_add |
0.11× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.prepared_auto |
0.120 | torch.sparse.mm |
2.48× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.auto |
0.130 | torch.sparse.mm |
2.28× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.reference |
5.638 | torch.sparse.mm |
0.05× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.sparse.mm |
0.298 | torch.sparse.mm |
1.00× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | triton.csr |
0.485 | torch.sparse.mm |
0.61× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.compile.index_add |
0.593 | torch.sparse.mm |
0.50× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | pyg.message_passing |
3.571 | torch.sparse.mm |
0.08× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.index_add |
4.216 | torch.sparse.mm |
0.07× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | tiga.prepared_auto |
0.057 | torch.sparse.mm |
4.63× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | tiga.auto |
0.090 | torch.sparse.mm |
2.91× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | tiga.reference |
3.061 | torch.sparse.mm |
0.09× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | torch.sparse.mm |
0.263 | torch.sparse.mm |
1.00× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | torch.compile.index_add |
0.278 | torch.sparse.mm |
0.95× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | triton.csr |
0.388 | torch.sparse.mm |
0.68× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | pyg.message_passing |
1.673 | torch.sparse.mm |
0.16× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | torch.index_add |
1.776 | torch.sparse.mm |
0.15× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | tiga.prepared_auto |
0.206 | torch.sparse.mm |
1.94× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | tiga.auto |
0.235 | torch.sparse.mm |
1.70× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | tiga.reference |
5.711 | torch.sparse.mm |
0.07× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | torch.sparse.mm |
0.400 | torch.sparse.mm |
1.00× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | triton.csr |
0.413 | torch.sparse.mm |
0.97× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | torch.compile.index_add |
0.669 | torch.sparse.mm |
0.60× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | pyg.message_passing |
3.540 | torch.sparse.mm |
0.11× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | torch.index_add |
4.253 | torch.sparse.mm |
0.09× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | tiga.prepared_auto |
0.077 | torch.sparse.mm |
3.24× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | tiga.auto |
0.088 | torch.sparse.mm |
2.86× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | tiga.reference |
3.016 | torch.sparse.mm |
0.08× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | torch.sparse.mm |
0.251 | torch.sparse.mm |
1.00× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | torch.compile.index_add |
0.332 | torch.sparse.mm |
0.75× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | triton.csr |
0.381 | torch.sparse.mm |
0.66× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | pyg.message_passing |
1.665 | torch.sparse.mm |
0.15× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | torch.index_add |
1.788 | torch.sparse.mm |
0.14× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | tiga.prepared_auto |
0.313 | torch.sparse.mm |
1.19× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | tiga.auto |
0.319 | torch.sparse.mm |
1.17× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | tiga.reference |
5.708 | torch.sparse.mm |
0.07× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | torch.sparse.mm |
0.373 | torch.sparse.mm |
1.00× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | triton.csr |
0.445 | torch.sparse.mm |
0.84× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | torch.compile.index_add |
0.695 | torch.sparse.mm |
0.54× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | pyg.message_passing |
3.559 | torch.sparse.mm |
0.10× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | torch.index_add |
4.276 | torch.sparse.mm |
0.09× |
radius_edge_mlp
PointNet++-style edge-local MLP message passing on a radius relation (MLP 11→16→8, FP32): the MLP is captured with tg.nn.trace and compiled into a fused tile kernel. Peers are a handwritten Triton tile oracle, a handwritten NVIDIA Warp fused kernel and the PyTorch eager gather → MLP → index_add fallback.
| Case | Bucket | Provider | Median (ms) | Peer | Speedup vs peer |
|---|---|---|---|---|---|
n262144 |
hot · F8 | tiga-compiled-tile |
1.020 | warp-fused |
8.50× |
n262144 |
hot · F8 | tiga-eager |
13.058 | warp-fused |
0.66× |
n262144 |
hot · F8 | triton-fused-tile |
1.017 | warp-fused |
8.53× |
n262144 |
hot · F8 | warp-fused |
8.670 | warp-fused |
1.00× |
n262144 |
hot · F8 | torch-eager |
12.069 | warp-fused |
0.72× |
edge_nn_backward
One forward+backward training step of the edge-local MLP: the backward is a compiler-derived symbolic-VJP recompute tile, so no [E, ·] activation is materialized. The peer is eager Torch autograd.
| Case | Bucket | Provider | Median (ms) | Peer | Speedup vs peer |
|---|---|---|---|---|---|
cuda_n131072_degree32 |
— | tiga.fused_recompute_vjp |
2.991 | torch.eager_autograd |
13.45× |
cuda_n131072_degree32 |
— | torch.eager_autograd |
40.227 | torch.eager_autograd |
1.00× |
diffusion
Sparse anisotropic diffusion steps on local and random graph slices across degrees 2–64. Each case separates compiler-generated Tiga points from benchmark-only peers such as torch.sparse_laplacian, torch.index_add and triton.csr.
| Case | Bucket | Candidate (ms) | Baseline (ms) | Speedup | 95% CI | Gate |
|---|---|---|---|---|---|---|
regular_local_cuda_i64_n131072_degree2 |
regular · local · hot · F1 | tiga.auto 0.018 |
torch.index_add 0.036 |
1.99× | [1.98, 2.01] | pass |
regular_local_cuda_i64_n131072_degree4 |
regular · local · hot · F1 | tiga.auto 0.018 |
torch.index_add 0.036 |
2.04× | [2.03, 2.07] | pass |
regular_local_cuda_i64_n131072_degree8 |
regular · local · hot · F1 | tiga.auto 0.017 |
torch.sparse_laplacian 0.036 |
2.09× | [2.05, 2.11] | pass |
regular_local_cuda_i64_n131072_degree16 |
regular · local · hot · F1 | tiga.auto 0.024 |
torch.sparse_laplacian 0.037 |
1.51× | [1.48, 1.54] | pass |
regular_local_cuda_i64_n131072_degree32 |
regular · local · hot · F1 | tiga.auto 0.052 |
torch.sparse_laplacian 0.081 |
1.55× | [1.53, 1.56] | pass |
regular_local_cuda_i64_n131072_degree64 |
regular · local · hot · F1 | tiga.auto 0.134 |
torch.sparse_laplacian 0.144 |
1.07× | [1.07, 1.07] | pass |
irregular_local_cuda_i64_n131072_degree16 |
irregular · local · hot · F1 | tiga.auto 0.034 |
torch.sparse_laplacian 0.037 |
1.07× | [1.05, 1.08] | pass |
skewed_local_cuda_i64_n131072_degree16 |
skewed · local · hot · F1 | tiga.auto 0.035 |
torch.sparse_laplacian 0.036 |
1.03× | [1.02, 1.05] | pass |
regular_random_cuda_i64_n8192_degree16 |
regular · random · hot · F1 | tiga.auto 0.026 |
triton.csr 0.032 |
1.23× | [1.01, 1.33] | pass |
radius_graph_build
Building the radius relation itself from positions: a generated cell directory versus materialized cell-list/CSR construction. Useful FLOPs count exact candidate distance tests only.
| Case | Bucket | Provider | Median (ms) | Peer | Speedup vs peer |
|---|---|---|---|---|---|
cuda_n32768_d3_degree32 |
radius · spatial · build-only · F1 · nodes=32768 · edges=978044 · index_dtype=int64 | tiga.compact_cell_directory |
0.335 | tiga.materialized_cell_list_csr |
9.46× |
cuda_n32768_d3_degree32 |
radius · spatial · build-only · F1 · nodes=32768 · edges=978044 · index_dtype=int64 | tiga.materialized_cell_list_csr |
3.171 | tiga.materialized_cell_list_csr |
1.00× |
radius_distance_aggregation
Distance-weighted aggregation on a radius graph, reported separately for the consume, relation-reuse and fresh build+consume phases. Peers are the materialized CSR pipeline and torch.sparse.mm.
| Case | Bucket | Provider | Median (ms) | Peer | Speedup vs peer |
|---|---|---|---|---|---|
cuda_n32768_d3_degree32 |
radius · spatial · consumer-only · F1 · nodes=32768 · edges=978044 · index_dtype=int64 | tiga.direct_ttir_generated |
0.334 | torch.sparse.precomputed_distance |
0.13× |
cuda_n32768_d3_degree32 |
radius · spatial · consumer-only · F1 · nodes=32768 · edges=978044 · index_dtype=int64 | tiga.triton_generated_oracle |
0.338 | torch.sparse.precomputed_distance |
0.13× |
cuda_n32768_d3_degree32 |
radius · spatial · consumer-only · F1 · nodes=32768 · edges=978044 · index_dtype=int64 | torch.sparse.precomputed_distance |
0.044 | torch.sparse.precomputed_distance |
1.00× |
cuda_n32768_d3_degree32 |
radius · spatial · consumer-only · F1 · nodes=32768 · edges=978044 · index_dtype=int64 | tiga.materialized_csr |
0.058 | torch.sparse.precomputed_distance |
0.76× |
cuda_n32768_d3_degree32 |
radius · spatial · relation-reuse · F1 · nodes=32768 · edges=978044 · index_dtype=int64 | tiga.dynamic_auto |
0.048 | tiga.materialized_reuse |
1.30× |
cuda_n32768_d3_degree32 |
radius · spatial · relation-reuse · F1 · nodes=32768 · edges=978044 · index_dtype=int64 | tiga.materialized_reuse |
0.062 | tiga.materialized_reuse |
1.00× |
cuda_n32768_d3_degree32 |
radius · spatial · fresh-build+consume · F1 · nodes=32768 · edges=978044 · index_dtype=int64 | tiga.generated_build_consume |
0.734 | tiga.materialized_build_consume |
4.43× |
cuda_n32768_d3_degree32 |
radius · spatial · fresh-build+consume · F1 · nodes=32768 · edges=978044 · index_dtype=int64 | tiga.materialized_build_consume |
3.247 | tiga.materialized_build_consume |
1.00× |
online_softmax
A numerically stable online-softmax reducer written in reducer algebra and reassociated to one TTIR tile. The peer is a matched handwritten fused Triton kernel.
| Case | Bucket | Candidate (ms) | Baseline (ms) | Speedup | 95% CI | Gate |
|---|---|---|---|---|---|---|
cuda_n131072_degree32_f1 |
fixed-degree-csr · random · hot · F1 | tiga.compiler_ttir 0.168 |
triton.handwritten_fused 0.169 |
1.01× | [1.01, 1.01] | pass |
knn_graph
Exact kNN graph build fused with the consuming reduction — no N×N distance matrix or CSR is materialized. The peer is torch.cdist_topk_gather_sum.
| Case | Bucket | Candidate (ms) | Baseline (ms) | Speedup | 95% CI | Gate |
|---|---|---|---|---|---|---|
cuda_n8192_d3_k32_consume |
uniform-random · all-pairs · hot · F3 | tiga.knn_build_consume_prepared_ttir 2.950 |
torch.cdist_topk_gather_sum 3.915 |
1.33× | [1.33, 1.33] | pass |
cuda_n4096_d5_k16_consume |
uniform-random · all-pairs · hot · F5 | tiga.knn_build_consume_prepared_ttir 0.659 |
torch.cdist_topk_gather_sum 1.071 |
1.63× | [1.62, 1.63] | pass |
cuda_n4096_d5_k13_consume |
uniform-random · all-pairs · hot · F5 | tiga.knn_build_consume_prepared_ttir 0.663 |
torch.cdist_topk_gather_sum 1.074 |
1.62× | [1.62, 1.63] | pass |
dense_matmul_calibration
Dense matmul calibration gate: the compiler auto-selects a Torch-free cuBLASLt runtime path and is gated against torch.mm/cuBLAS.
| Case | Bucket | Candidate (ms) | Baseline (ms) | Speedup | 95% CI | Gate |
|---|---|---|---|---|---|---|
m2048_n2048_k2048_fp16 |
dense · contiguous · hot · F2048 | tiga.compiler_auto 0.192 |
torch.mm.cublas 0.193 |
1.00× | [1.00, 1.01] | pass |
dense_attention
Exact dense attention written as MessagePassing and lowered through Domain, Iter and Kernel IR to compiler-emitted TTIR (full Cartesian, causal and grouped-query relations). The peer is Flash SDPA (torch.sdpa.flash).
| Case | Bucket | Candidate (ms) | Baseline (ms) | Speedup | 95% CI | Gate |
|---|---|---|---|---|---|---|
b1_h16_n4096_d64_fp16 |
cartesian · dense · consumer-only · F64 | tiga.direct_ttir 0.772 |
torch.sdpa.flash 0.829 |
1.07× | [1.07, 1.08] | pass |
b1_h16_n4096_d64_fp16_causal |
lower-triangular · dense · consumer-only · F64 | tiga.direct_ttir 0.446 |
torch.sdpa.flash 0.498 |
1.12× | [1.10, 1.13] | pass |
b1_h16_n4096_d64_fp16_kvh4 |
cartesian · dense · consumer-only · F64 | tiga.direct_ttir 0.777 |
torch.sdpa.flash 0.842 |
1.08× | [1.08, 1.09] | pass |
horizontal_fusion
Horizontal fusion of sibling message-passing kernels over one shared relation. The peer is a matched handwritten fused Triton oracle.
| Case | Bucket | Candidate (ms) | Baseline (ms) | Speedup | 95% CI | Gate |
|---|---|---|---|---|---|---|
cuda_n131072_degree16_i64 |
regular · local · hot · F1 | tiga.compiler_fused 0.022 |
triton.fused_oracle 0.023 |
1.05× | [1.04, 1.06] | pass |
message_passing_backward
Compiler-derived VJPs of forward message-passing UDFs, including a zero-safe product-reducer VJP and a radius-geometry backward. Peers are matched handwritten Triton kernels and torch.autograd.
| Case | Bucket | Candidate (ms) | Baseline (ms) | Speedup | 95% CI | Gate |
|---|---|---|---|---|---|---|
regular_random_cuda_i64_n131072_degree16_dx |
regular · random · hot · F1 | tiga.generated_vjp 0.058 |
handwritten.triton 0.059 |
1.01× | [1.01, 1.02] | pass |
regular_random_cuda_i64_n131072_degree16_dweight |
regular · random · hot · F1 | tiga.generated_vjp 0.016 |
handwritten.triton.saved 0.020 |
1.25× | [1.25, 1.26] | pass |
regular_random_cuda_i64_n131072_degree16_dweight_f16 |
regular · random · hot · F16 | tiga.generated_vjp 2.054 |
handwritten.triton.saved 2.060 |
1.00× | [1.00, 1.00] | pass |
regular_random_cuda_i64_n131072_degree16_dweight_f64 |
regular · random · hot · F64 | tiga.generated_vjp 2.304 |
handwritten.triton.saved 2.313 |
1.00× | [1.00, 1.00] | pass |
powerlaw_random_cuda_i64_n131072_degree16_dx |
powerlaw · random · hot · F1 | tiga.generated_vjp 0.057 |
handwritten.triton 0.059 |
1.03× | [1.03, 1.04] | pass |
powerlaw_random_cuda_i64_n131072_degree16_dweight_f16 |
powerlaw · random · hot · F16 | tiga.generated_vjp 1.996 |
handwritten.triton.saved 2.005 |
1.00× | [1.00, 1.01] | pass |
regular_edge_local_cuda_i64_n131072_degree16_product |
regular · edge-local · hot · F1 | tiga.generated_vjp 0.072 |
handwritten.triton 0.073 |
1.02× | [1.02, 1.03] | pass |
radius_fixed_snapshot_cuda_n32768_d3_degree32 |
radius-fixed-snapshot · cell-list · hot · F4 | tiga.generated_vjp 0.240 |
handwritten.triton 0.259 |
1.08× | [1.07, 1.08] | pass |
linear_attention
Causal linear attention as an unnormalized recurrence, fused into one scan TTIR kernel; the rank-four prefix state is never materialized. The peer is the official FLA implementation.
| Case | Bucket | Candidate (ms) | Baseline (ms) | Speedup | 95% CI | Gate |
|---|---|---|---|---|---|---|
l64_t512_k16_v16_fp32 |
causal-prefix · dense-state · hot · F256 | tiga.compiler_scan_contract 0.106 |
fla.chunk 0.109 |
1.04× | [1.02, 1.05] | pass |
sparse_attention
Tile-pruned sparse attention with a semantic admission threshold that survives reducer IR into generic dense streaming lowering. The peer is the official flash-sparse-attn kernel at the same pruning threshold.
| Case | Bucket | Candidate (ms) | Baseline (ms) | Speedup | 95% CI | Gate |
|---|---|---|---|---|---|---|
b1_h16_n4096_d64_fp16 |
dynamic-score-tile · dense · hot · F64 | tiga.compiler_tile_pruned 0.907 |
flash_sparse_attn.official 1.072 |
1.18× | [1.18, 1.19] | pass |
cpu_pointwise_fusion
CPU Tensor pointwise fusion lowered to 512-bit LLVM vectors on a lazily-created persistent worker pool. The peer is torch.compile/Inductor.
| Case | Bucket | Candidate (ms) | Baseline (ms) | Speedup | 95% CI | Gate |
|---|---|---|---|---|---|---|
n4000000_f32_t16 |
contiguous · local · cold · F1 | tiga.llvm.vector_parallel 0.951 |
torch.compile.inductor 1.020 |
1.07× | [1.05, 1.12] | pass |
cpu_relation
CPU fused relation loop: gather, UDF and CSR-reduce in one nested 16-thread LLVM loop. Peers are scipy.csr_matvec and torch.sparse.mm on CPU.
| Case | Bucket | Candidate (ms) | Baseline (ms) | Speedup | 95% CI | Gate |
|---|---|---|---|---|---|---|
regular_permuted_i32_n131072_degree16_t16 |
regular · permuted · hot · F1 | tiga.llvm.parallel_relation 0.124 |
scipy.csr_matvec 0.781 |
6.32× | [5.54, 6.66] | pass |
pagerank
Fixed-iteration PageRank captured as one gf_control.repeat recurrence with a fused per-iteration TTIR kernel and two ping-pong buffers. The peer is an identical fixed-iteration torch.sparse.mm recurrence.
| Case | Bucket | Candidate (ms) | Baseline (ms) | Speedup | 95% CI | Gate |
|---|---|---|---|---|---|---|
cuda_fp32_iter20 |
regular-degree-16 · cyclic · hot · F1 · N262144 | tiga.control 0.590 |
torch.sparse.mm 1.379 |
2.34× | [2.31, 2.52] | pass |
cuda_fp32_iter20 |
regular-degree-16 · cyclic · hot · F1 · N65536 | tiga.control 0.190 |
torch.sparse.mm 0.352 |
1.85× | [1.82, 1.88] | pass |
cuda_fp32_iter20 |
regular-degree-32 · cyclic · hot · F1 · N262144 | tiga.control 2.462 |
torch.sparse.mm 2.583 |
1.05× | [1.04, 1.05] | pass |
cuda_fp32_iter20 |
regular-degree-32 · cyclic · hot · F1 · N65536 | tiga.control 0.244 |
torch.sparse.mm 0.380 |
1.56× | [1.54, 1.58] | pass |
cuda_fp32_iter20 |
regular-degree-4 · cyclic · hot · F1 · N262144 | tiga.control 0.217 |
torch.sparse.mm 0.357 |
1.64× | [1.61, 1.67] | pass |
cuda_fp32_iter20 |
regular-degree-4 · cyclic · hot · F1 · N65536 | tiga.control 0.190 |
torch.sparse.mm 0.354 |
1.86× | [1.83, 1.92] | pass |
visualization_heatmap
Scalar-field → RGB heatmap preparation composed from ordinary Tensor IR. The peer is torch.compile/Inductor.
| Case | Bucket | Candidate (ms) | Baseline (ms) | Speedup | 95% CI | Gate |
|---|---|---|---|---|---|---|
h2048_w2048_rgb_f32 |
image-grid · contiguous · consumer-only · F3 | tiga.tensor_ttir 0.100 |
torch.inductor.fused 0.115 |
1.15× | [1.14, 1.17] | pass |