基准结果
运行时间与内存对比、大图容量和分布式开销见性能与扩展性。本页为历史测量归档。
本页是历史测量,不是当前 checkout 的性能结果。存档包含 18 个 operation 的 44 个已注册 case,以及六个辅助数据文件。GPU 数据来自记录中的 RTX 5070 Ti 环境,CPU 数据属于配套主机;不计算跨设备综合分数。
范围与来源
部分历史文件缺少原始代码 revision、驱动/包版本或逐次采样。存档可以复现图表,但不保证新测量得到相同性能。--quick 是 smoke 测量,不是所有存档 case 的精确复现命令。
怎样读图
新的大图容量测量单列于十亿边实验。 它的完整前向计时不能与下方历史 warm operator 计时混用。
加速比大于 1 表示指定候选快于该行对标实现,图中同时保留毫秒数。不同工作负载、不同计时边界的比值不取平均。F 是 feature 宽度,不是浮点精度;内存图区分逐边中间量估算和实测峰值分配。小屏幕可横向滚动图表;点击图可打开完整 SVG。
GPU
Weighted CSR aggregation 对每个目标行计算加权和。选中的拓扑切片为 131,072 行、平均度 16、FP32 数值;索引宽度以各存档 case 为准。F=1/16/64 表示 feature 宽度。
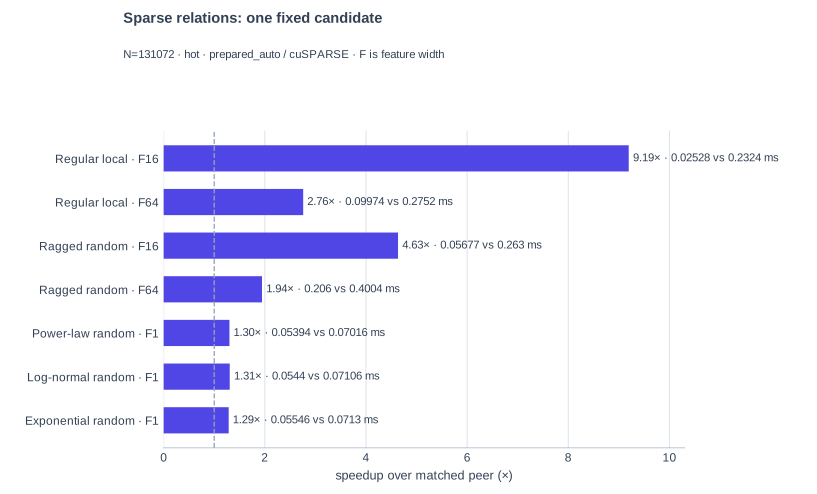
候选为 tiga.prepared_auto,对标为 torch.sparse.mm,cache 为 hot;准备阶段不计入这个 warm 时间。这是固定切片,不代表所有已注册拓扑都获胜。全部稀疏 case。
边 MLP 读取相对位置和源节点 feature,再按目标聚合。融合与 eager 路径计算同一个选定工作负载;手写 Triton tile 是 oracle,不是编译器生成代码。
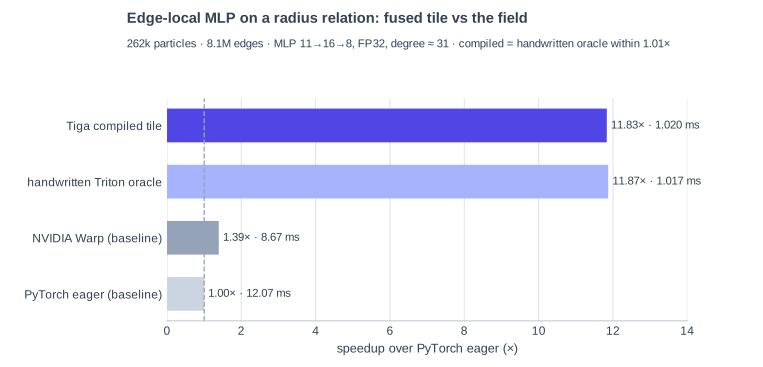
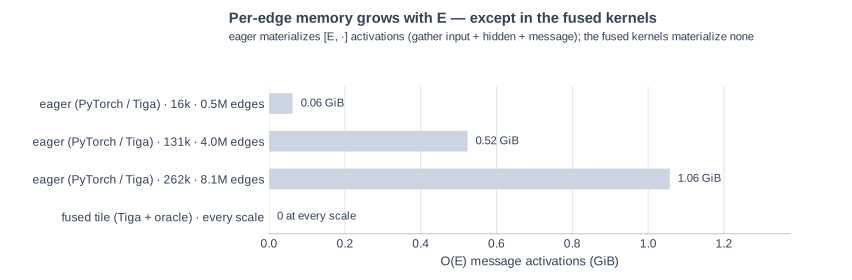
第二张图的零表示不物化逐边 activation 数组,不是总设备内存为零。GiB 来自中间 Tensor 尺寸估算,不是 allocator 峰值测量。
这个图 attention case 包含逐边评分、按目标归一化和聚合,不是 dense SDPA。
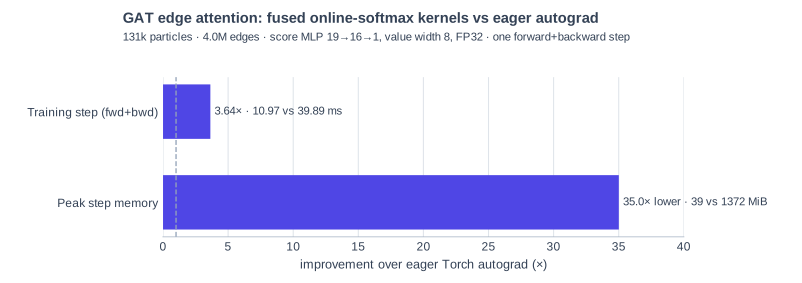
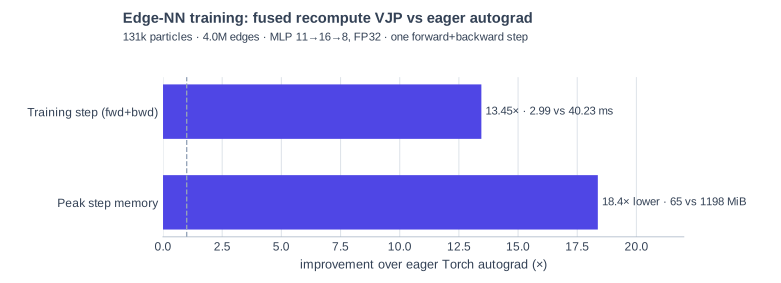
对标为同一个已记录图上的 eager autograd。这是辅助存档,不在 44 个已注册 case 中;准确输入路径见逐图索引。
Dense exact、linear、tile-pruned sparse attention 是不同的数学工作负载。每行只与自己的匹配实现比较,跨行不能用于排名。
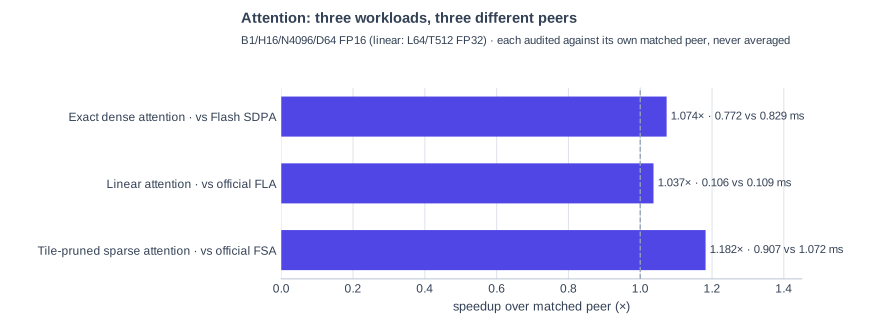
Dense case · Linear case · Sparse case。完整矩阵给出 shape、精度和 provider 名称。
编译器整体
以下每行都选择明确的存档工作负载及匹配基线。选择由生成器固定,不会自动扫描最大加速比。
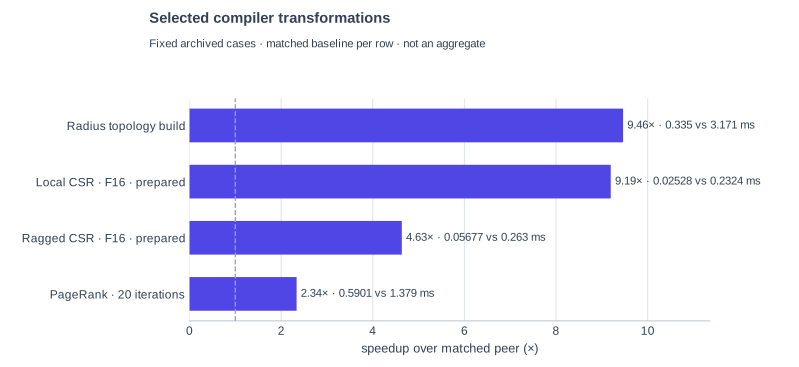
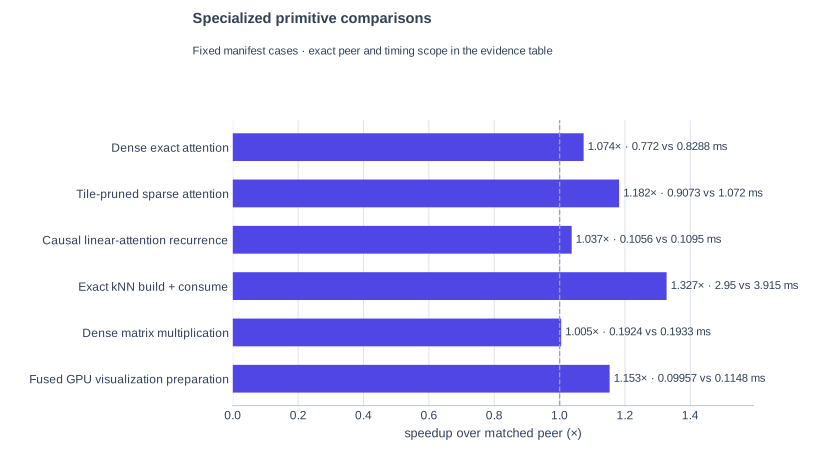
基线名称和精确筛选条件见 benchmarks/evidence_manifest.json 与 benchmarks/common/plot_docs_results.py;条形旁保留候选/对标的绝对时延。PageRank · kNN · Matmul 校准 · Heatmap。
CPU
同一个 FP32/i32、度 16 的 relation loop,在两种节点数下对比 SciPy CSR matvec 与 Torch sparse,线程数为 16;同时呈现胜出与落后的切片。
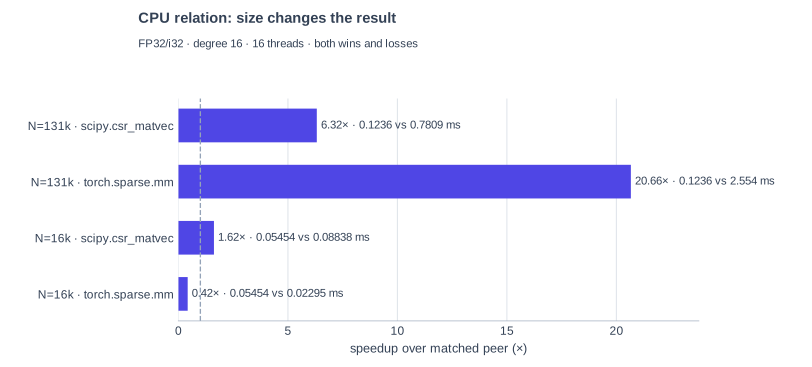
131k case 已注册,16k 对比属于辅助存档。此结果不能证明跨 CPU、线程数或 NUMA placement 的扩展性。已注册 CPU relation。
历史内部 overlap 探测,不代表公开执行策略(固定先通信、再计算)。两个 CPU 进程使用人为增加延迟的传输链路;这不是 NVLink、RDMA 或多 GPU 基准。
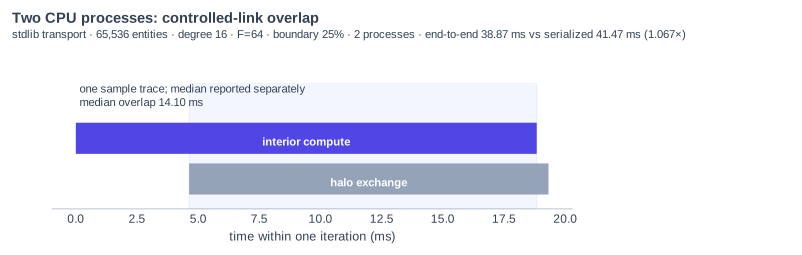
时间线取某个 rank 的首个 sample,中位数标注来自完整采样集合;不表示每次采样的重叠均相同。可运行分布式例子。
完整矩阵
表格从同一批已注册存档输入生成,包含较慢路径。这是详细证据视图,不是另一批独立测量;每个 operation 列出 case 条件、计时范围和对标实现。
邻居加权求和
计算内容:每个节点收集邻居的值,乘上边权后求和。下面固定比较 tiga.prepared_auto 与 torch.sparse.mm,只展示 hot 数据缓存;所有已注册图类型和 feature 宽度都保留,不挑最快的一行。
所有行均为 131,072 个节点、FP32 数值。F 是每个节点的数值个数,i32/i64 是节点索引的整数位宽,不是数值精度。耗时越小越好;加速比 = 对标耗时 ÷ Tiga 耗时,低于 1 表示 Tiga 更慢。
| 图类型 | 邻居分布 | 索引 | F | Tiga(ms) | Torch sparse(ms) | 加速比 |
|---|---|---|---|---|---|---|
| 等度 | 编号相近 | i64 | 1 | 0.020 | 0.047 | 2.31× |
| 等度 | 编号相近 | i64 | 16 | 0.025 | 0.232 | 9.19× |
| 等度 | 编号相近 | i64 | 64 | 0.100 | 0.275 | 2.76× |
| 不等度 | 随机编号 | i32 | 16 | 0.057 | 0.263 | 4.63× |
| 不等度 | 随机编号 | i32 | 64 | 0.206 | 0.400 | 1.94× |
| 幂律 | 编号相近 | i32 | 1 | 0.020 | 0.041 | 2.00× |
| 幂律 | 编号相近 | i64 | 1 | 0.023 | 0.038 | 1.65× |
| 幂律 | 随机编号 | i32 | 1 | 0.054 | 0.070 | 1.30× |
| 幂律 | 随机编号 | i64 | 1 | 0.054 | 0.071 | 1.32× |
| 对数正态 | 随机编号 | i32 | 1 | 0.054 | 0.071 | 1.31× |
| 指数 | 随机编号 | i32 | 1 | 0.055 | 0.071 | 1.29× |
等度表示每个节点的邻居数相同;其余图类型让邻居数量变化,用于检查负载不均衡。local/random 描述源节点编号是否集中,不代表跨机器通信。
prepared_auto 已提前完成绑定/准备;计时不含首次编译、准备和建图。hot 是反复使用数据,cold 是测量前主动扰动数据缓存;cold 不是首次 JIT 编译。这些历史路径不等于当前普通 Torch 调用的端到端性能。
下方保留全部原始实现与 hot/cold 结果。95% 置信区间描述采样的不确定性;“性能检查通过”表示达到该存档阈值,不表示所有功能正确或已经可以发布。
全部测量与实现细节
| 存档用例 | 测试条件 | 被测实现(ms) | 对标实现(ms) | 加速比 | 加速比的 95% 置信区间 | 性能检查 |
|---|---|---|---|---|---|---|
powerlaw_local_cuda_i32_n131072_degree16_f1 |
powerlaw · local · hot · F1 · N131072 | tiga.compiler_chunked_tail 0.027 |
torch.sparse.mm 0.041 |
1.51× | [1.39, 1.71] | 通过 |
powerlaw_local_cuda_i32_n131072_degree16_f1 |
powerlaw · local · hot · F1 · N131072 | tiga.prepared_auto 0.020 |
torch.sparse.mm 0.041 |
2.00× | [1.89, 2.30] | 通过 |
powerlaw_local_cuda_i32_n131072_degree16_f1 |
powerlaw · local · cold · F1 · N131072 | tiga.compiler_chunked_tail 0.051 |
torch.sparse.mm 0.071 |
1.39× | [1.36, 1.50] | 通过 |
powerlaw_local_cuda_i32_n131072_degree16_f1 |
powerlaw · local · cold · F1 · N131072 | tiga.prepared_auto 0.051 |
torch.sparse.mm 0.071 |
1.40× | [1.35, 1.51] | 通过 |
powerlaw_local_cuda_i64_n131072_degree16_f1 |
powerlaw · local · hot · F1 | tiga.prepared_auto 0.023 |
torch.sparse.mm 0.038 |
1.65× | [1.63, 1.72] | 通过 |
powerlaw_local_cuda_i64_n131072_degree16_f1 |
powerlaw · local · cold · F1 | tiga.prepared_auto 0.061 |
torch.sparse.mm 0.082 |
1.33× | [1.30, 1.44] | 通过 |
powerlaw_random_cuda_i32_n131072_degree16_f1 |
powerlaw · random · hot · F1 · N131072 | tiga.compiler_chunked_tail 0.054 |
torch.sparse.mm 0.070 |
1.31× | [1.28, 1.33] | 通过 |
powerlaw_random_cuda_i32_n131072_degree16_f1 |
powerlaw · random · hot · F1 · N131072 | tiga.prepared_auto 0.054 |
torch.sparse.mm 0.070 |
1.30× | [1.27, 1.32] | 通过 |
powerlaw_random_cuda_i32_n131072_degree16_f1 |
powerlaw · random · cold · F1 · N131072 | tiga.compiler_chunked_tail 0.059 |
torch.sparse.mm 0.086 |
1.46× | [1.45, 1.49] | 通过 |
powerlaw_random_cuda_i32_n131072_degree16_f1 |
powerlaw · random · cold · F1 · N131072 | tiga.prepared_auto 0.059 |
torch.sparse.mm 0.086 |
1.45× | [1.42, 1.47] | 通过 |
powerlaw_random_cuda_i64_n131072_degree16_f1 |
powerlaw · random · hot · F1 | tiga.prepared_auto 0.054 |
torch.sparse.mm 0.071 |
1.32× | [1.28, 1.35] | 通过 |
powerlaw_random_cuda_i64_n131072_degree16_f1 |
powerlaw · random · cold · F1 | tiga.prepared_auto 0.079 |
torch.sparse.mm 0.095 |
1.20× | [1.19, 1.21] | 通过 |
lognormal_random_cuda_i32_n131072_degree16_f1 |
lognormal · random · hot · F1 · N131072 | tiga.compiler_chunked_tail 0.059 |
torch.sparse.mm 0.071 |
1.20× | [1.17, 1.23] | 通过 |
lognormal_random_cuda_i32_n131072_degree16_f1 |
lognormal · random · hot · F1 · N131072 | tiga.prepared_auto 0.054 |
torch.sparse.mm 0.071 |
1.31× | [1.26, 1.34] | 通过 |
lognormal_random_cuda_i32_n131072_degree16_f1 |
lognormal · random · cold · F1 · N131072 | tiga.compiler_chunked_tail 0.076 |
torch.sparse.mm 0.086 |
1.12× | [1.11, 1.13] | 通过 |
lognormal_random_cuda_i32_n131072_degree16_f1 |
lognormal · random · cold · F1 · N131072 | tiga.prepared_auto 0.070 |
torch.sparse.mm 0.086 |
1.22× | [1.20, 1.23] | 通过 |
exponential_random_cuda_i32_n131072_degree16_f1 |
exponential · random · hot · F1 · N131072 | tiga.compiler_chunked_tail 0.059 |
torch.sparse.mm 0.071 |
1.20× | [1.18, 1.23] | 通过 |
exponential_random_cuda_i32_n131072_degree16_f1 |
exponential · random · hot · F1 · N131072 | tiga.prepared_auto 0.055 |
torch.sparse.mm 0.071 |
1.29× | [1.26, 1.31] | 通过 |
exponential_random_cuda_i32_n131072_degree16_f1 |
exponential · random · cold · F1 · N131072 | tiga.compiler_chunked_tail 0.075 |
torch.sparse.mm 0.087 |
1.15× | [1.14, 1.17] | 通过 |
exponential_random_cuda_i32_n131072_degree16_f1 |
exponential · random · cold · F1 · N131072 | tiga.prepared_auto 0.071 |
torch.sparse.mm 0.087 |
1.23× | [1.21, 1.25] | 通过 |
以下用例没有存档性能检查;每行是一种实测实现。对标优先采用预先指定的实现,否则采用相同测试条件下最快的非 Tiga 实现。
| 存档用例 | 测试条件 | 执行实现 | 中位耗时(ms) | 对标实现 | 相对加速比 |
|---|---|---|---|---|---|
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.prepared_auto |
0.020 | torch.sparse.mm |
2.31× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.auto |
0.046 | torch.sparse.mm |
1.03× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.reference |
0.216 | torch.sparse.mm |
0.22× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.sparse.mm |
0.047 | torch.sparse.mm |
1.00× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.compile.index_add |
0.083 | torch.sparse.mm |
0.57× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.index_add |
0.084 | torch.sparse.mm |
0.56× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | triton.csr |
0.379 | torch.sparse.mm |
0.12× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.prepared_auto |
0.025 | torch.sparse.mm |
9.19× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.auto |
0.062 | torch.sparse.mm |
3.77× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.reference |
3.115 | torch.sparse.mm |
0.07× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.sparse.mm |
0.232 | torch.sparse.mm |
1.00× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.compile.index_add |
0.234 | torch.sparse.mm |
0.99× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | triton.csr |
0.427 | torch.sparse.mm |
0.54× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | pyg.message_passing |
1.748 | torch.sparse.mm |
0.13× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.index_add |
1.832 | torch.sparse.mm |
0.13× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.auto |
0.095 | torch.sparse.mm |
2.89× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.prepared_auto |
0.100 | torch.sparse.mm |
2.76× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.reference |
5.621 | torch.sparse.mm |
0.05× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.sparse.mm |
0.275 | torch.sparse.mm |
1.00× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | triton.csr |
0.453 | torch.sparse.mm |
0.61× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.compile.index_add |
0.577 | torch.sparse.mm |
0.48× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | pyg.message_passing |
3.561 | torch.sparse.mm |
0.08× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · hot · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.index_add |
4.188 | torch.sparse.mm |
0.07× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.prepared_auto |
0.046 | torch.sparse.mm |
1.72× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.auto |
0.055 | torch.sparse.mm |
1.43× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.reference |
0.216 | torch.sparse.mm |
0.36× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.sparse.mm |
0.079 | torch.sparse.mm |
1.00× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.index_add |
0.113 | torch.sparse.mm |
0.70× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.compile.index_add |
0.115 | torch.sparse.mm |
0.68× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F1 · nodes=131072 · edges=2097152 · index_dtype=i64 | triton.csr |
0.387 | torch.sparse.mm |
0.20× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.prepared_auto |
0.058 | torch.compile.index_add |
3.40× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.auto |
0.067 | torch.compile.index_add |
2.95× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.reference |
3.098 | torch.compile.index_add |
0.06× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.compile.index_add |
0.197 | torch.compile.index_add |
1.00× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.sparse.mm |
0.233 | torch.compile.index_add |
0.84× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | triton.csr |
0.449 | torch.compile.index_add |
0.44× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | pyg.message_passing |
1.748 | torch.compile.index_add |
0.11× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F16 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.index_add |
1.841 | torch.compile.index_add |
0.11× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.prepared_auto |
0.120 | torch.sparse.mm |
2.48× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.auto |
0.130 | torch.sparse.mm |
2.28× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | tiga.reference |
5.638 | torch.sparse.mm |
0.05× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.sparse.mm |
0.298 | torch.sparse.mm |
1.00× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | triton.csr |
0.485 | torch.sparse.mm |
0.61× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.compile.index_add |
0.593 | torch.sparse.mm |
0.50× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | pyg.message_passing |
3.571 | torch.sparse.mm |
0.08× |
regular_local_cuda_i64_n131072_degree16_f1_16_64 |
regular · local · cold · F64 · nodes=131072 · edges=2097152 · index_dtype=i64 | torch.index_add |
4.216 | torch.sparse.mm |
0.07× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | tiga.prepared_auto |
0.057 | torch.sparse.mm |
4.63× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | tiga.auto |
0.090 | torch.sparse.mm |
2.91× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | tiga.reference |
3.061 | torch.sparse.mm |
0.09× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | torch.sparse.mm |
0.263 | torch.sparse.mm |
1.00× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | torch.compile.index_add |
0.278 | torch.sparse.mm |
0.95× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | triton.csr |
0.388 | torch.sparse.mm |
0.68× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | pyg.message_passing |
1.673 | torch.sparse.mm |
0.16× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | torch.index_add |
1.776 | torch.sparse.mm |
0.15× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | tiga.prepared_auto |
0.206 | torch.sparse.mm |
1.94× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | tiga.auto |
0.235 | torch.sparse.mm |
1.70× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | tiga.reference |
5.711 | torch.sparse.mm |
0.07× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | torch.sparse.mm |
0.400 | torch.sparse.mm |
1.00× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | triton.csr |
0.413 | torch.sparse.mm |
0.97× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | torch.compile.index_add |
0.669 | torch.sparse.mm |
0.60× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | pyg.message_passing |
3.540 | torch.sparse.mm |
0.11× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · hot · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | torch.index_add |
4.253 | torch.sparse.mm |
0.09× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | tiga.prepared_auto |
0.077 | torch.sparse.mm |
3.24× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | tiga.auto |
0.088 | torch.sparse.mm |
2.86× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | tiga.reference |
3.016 | torch.sparse.mm |
0.08× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | torch.sparse.mm |
0.251 | torch.sparse.mm |
1.00× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | torch.compile.index_add |
0.332 | torch.sparse.mm |
0.75× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | triton.csr |
0.381 | torch.sparse.mm |
0.66× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | pyg.message_passing |
1.665 | torch.sparse.mm |
0.15× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F16 · nodes=131072 · edges=2097960 · index_dtype=i32 | torch.index_add |
1.788 | torch.sparse.mm |
0.14× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | tiga.prepared_auto |
0.313 | torch.sparse.mm |
1.19× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | tiga.auto |
0.319 | torch.sparse.mm |
1.17× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | tiga.reference |
5.708 | torch.sparse.mm |
0.07× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | torch.sparse.mm |
0.373 | torch.sparse.mm |
1.00× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | triton.csr |
0.445 | torch.sparse.mm |
0.84× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | torch.compile.index_add |
0.695 | torch.sparse.mm |
0.54× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | pyg.message_passing |
3.559 | torch.sparse.mm |
0.10× |
irregular_random_cuda_i32_n131072_degree16_f16_64 |
irregular · random · cold · F64 · nodes=131072 · edges=2097960 · index_dtype=i32 | torch.index_add |
4.276 | torch.sparse.mm |
0.09× |
radius_edge_mlp
PointNet++ 风格的边局部 MLP 消息传递,作用在半径关系上(MLP 11→16→8,FP32):MLP 由 tg.nn.trace 捕获并编译为融合 tile kernel。对标实现为手写 Triton tile oracle、手写 NVIDIA Warp 融合 kernel,以及 PyTorch eager 的 gather → MLP → index_add 回退。
| 存档用例 | 测试条件 | 执行实现 | 中位耗时(ms) | 对标实现 | 相对加速比 |
|---|---|---|---|---|---|
n262144 |
hot · F8 | tiga-compiled-tile |
1.020 | warp-fused |
8.50× |
n262144 |
hot · F8 | tiga-eager |
13.058 | warp-fused |
0.66× |
n262144 |
hot · F8 | triton-fused-tile |
1.017 | warp-fused |
8.53× |
n262144 |
hot · F8 | warp-fused |
8.670 | warp-fused |
1.00× |
n262144 |
hot · F8 | torch-eager |
12.069 | warp-fused |
0.72× |
edge_nn_backward
边局部 MLP 的一次前向+反向训练步:反向是编译器推导的符号 VJP 重算 tile,不物化任何 [E, ·] 激活。对标实现为 eager Torch autograd。
| 存档用例 | 测试条件 | 执行实现 | 中位耗时(ms) | 对标实现 | 相对加速比 |
|---|---|---|---|---|---|
cuda_n131072_degree32 |
— | tiga.fused_recompute_vjp |
2.991 | torch.eager_autograd |
13.45× |
cuda_n131072_degree32 |
— | torch.eager_autograd |
40.227 | torch.eager_autograd |
1.00× |
diffusion
在 local 与 random 图切片上、度 2–64 的稀疏各向异性扩散步。每个 case 将编译器生成的 Tiga 数据点与 torch.sparse_laplacian、torch.index_add、triton.csr 等仅用于基准的对标实现分开。
| 存档用例 | 测试条件 | 被测实现(ms) | 对标实现(ms) | 加速比 | 加速比的 95% 置信区间 | 性能检查 |
|---|---|---|---|---|---|---|
regular_local_cuda_i64_n131072_degree2 |
regular · local · hot · F1 | tiga.auto 0.018 |
torch.index_add 0.036 |
1.99× | [1.98, 2.01] | 通过 |
regular_local_cuda_i64_n131072_degree4 |
regular · local · hot · F1 | tiga.auto 0.018 |
torch.index_add 0.036 |
2.04× | [2.03, 2.07] | 通过 |
regular_local_cuda_i64_n131072_degree8 |
regular · local · hot · F1 | tiga.auto 0.017 |
torch.sparse_laplacian 0.036 |
2.09× | [2.05, 2.11] | 通过 |
regular_local_cuda_i64_n131072_degree16 |
regular · local · hot · F1 | tiga.auto 0.024 |
torch.sparse_laplacian 0.037 |
1.51× | [1.48, 1.54] | 通过 |
regular_local_cuda_i64_n131072_degree32 |
regular · local · hot · F1 | tiga.auto 0.052 |
torch.sparse_laplacian 0.081 |
1.55× | [1.53, 1.56] | 通过 |
regular_local_cuda_i64_n131072_degree64 |
regular · local · hot · F1 | tiga.auto 0.134 |
torch.sparse_laplacian 0.144 |
1.07× | [1.07, 1.07] | 通过 |
irregular_local_cuda_i64_n131072_degree16 |
irregular · local · hot · F1 | tiga.auto 0.034 |
torch.sparse_laplacian 0.037 |
1.07× | [1.05, 1.08] | 通过 |
skewed_local_cuda_i64_n131072_degree16 |
skewed · local · hot · F1 | tiga.auto 0.035 |
torch.sparse_laplacian 0.036 |
1.03× | [1.02, 1.05] | 通过 |
regular_random_cuda_i64_n8192_degree16 |
regular · random · hot · F1 | tiga.auto 0.026 |
triton.csr 0.032 |
1.23× | [1.01, 1.33] | 通过 |
radius_graph_build
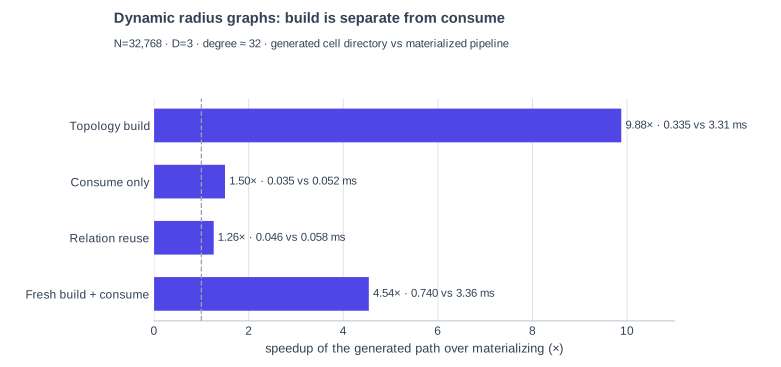
从位置构建半径关系本身:生成的 cell 目录对比物化的 cell-list/CSR 构建。有效 FLOPs 只计精确的候选距离测试。
| 存档用例 | 测试条件 | 执行实现 | 中位耗时(ms) | 对标实现 | 相对加速比 |
|---|---|---|---|---|---|
cuda_n32768_d3_degree32 |
radius · spatial · build-only · F1 · nodes=32768 · edges=978044 · index_dtype=int64 | tiga.compact_cell_directory |
0.335 | tiga.materialized_cell_list_csr |
9.46× |
cuda_n32768_d3_degree32 |
radius · spatial · build-only · F1 · nodes=32768 · edges=978044 · index_dtype=int64 | tiga.materialized_cell_list_csr |
3.171 | tiga.materialized_cell_list_csr |
1.00× |
radius_distance_aggregation
半径图上的距离加权聚合,按 consume、relation-reuse 与全新 build+consume 阶段分别报告。对标实现为物化 CSR 管线与 torch.sparse.mm。
| 存档用例 | 测试条件 | 执行实现 | 中位耗时(ms) | 对标实现 | 相对加速比 |
|---|---|---|---|---|---|
cuda_n32768_d3_degree32 |
radius · spatial · consumer-only · F1 · nodes=32768 · edges=978044 · index_dtype=int64 | tiga.direct_ttir_generated |
0.334 | torch.sparse.precomputed_distance |
0.13× |
cuda_n32768_d3_degree32 |
radius · spatial · consumer-only · F1 · nodes=32768 · edges=978044 · index_dtype=int64 | tiga.triton_generated_oracle |
0.338 | torch.sparse.precomputed_distance |
0.13× |
cuda_n32768_d3_degree32 |
radius · spatial · consumer-only · F1 · nodes=32768 · edges=978044 · index_dtype=int64 | torch.sparse.precomputed_distance |
0.044 | torch.sparse.precomputed_distance |
1.00× |
cuda_n32768_d3_degree32 |
radius · spatial · consumer-only · F1 · nodes=32768 · edges=978044 · index_dtype=int64 | tiga.materialized_csr |
0.058 | torch.sparse.precomputed_distance |
0.76× |
cuda_n32768_d3_degree32 |
radius · spatial · relation-reuse · F1 · nodes=32768 · edges=978044 · index_dtype=int64 | tiga.dynamic_auto |
0.048 | tiga.materialized_reuse |
1.30× |
cuda_n32768_d3_degree32 |
radius · spatial · relation-reuse · F1 · nodes=32768 · edges=978044 · index_dtype=int64 | tiga.materialized_reuse |
0.062 | tiga.materialized_reuse |
1.00× |
cuda_n32768_d3_degree32 |
radius · spatial · fresh-build+consume · F1 · nodes=32768 · edges=978044 · index_dtype=int64 | tiga.generated_build_consume |
0.734 | tiga.materialized_build_consume |
4.43× |
cuda_n32768_d3_degree32 |
radius · spatial · fresh-build+consume · F1 · nodes=32768 · edges=978044 · index_dtype=int64 | tiga.materialized_build_consume |
3.247 | tiga.materialized_build_consume |
1.00× |
online_softmax
以 reducer 代数写成的数值稳定 online softmax reducer,被重结合为单个 TTIR tile。对标实现为匹配的手写融合 Triton kernel。
| 存档用例 | 测试条件 | 被测实现(ms) | 对标实现(ms) | 加速比 | 加速比的 95% 置信区间 | 性能检查 |
|---|---|---|---|---|---|---|
cuda_n131072_degree32_f1 |
fixed-degree-csr · random · hot · F1 | tiga.compiler_ttir 0.168 |
triton.handwritten_fused 0.169 |
1.01× | [1.01, 1.01] | 通过 |
knn_graph
精确 kNN 图构建与消费归约融合——不物化 N×N 距离矩阵或 CSR。对标实现为 torch.cdist_topk_gather_sum。
| 存档用例 | 测试条件 | 被测实现(ms) | 对标实现(ms) | 加速比 | 加速比的 95% 置信区间 | 性能检查 |
|---|---|---|---|---|---|---|
cuda_n8192_d3_k32_consume |
uniform-random · all-pairs · hot · F3 | tiga.knn_build_consume_prepared_ttir 2.950 |
torch.cdist_topk_gather_sum 3.915 |
1.33× | [1.33, 1.33] | 通过 |
cuda_n4096_d5_k16_consume |
uniform-random · all-pairs · hot · F5 | tiga.knn_build_consume_prepared_ttir 0.659 |
torch.cdist_topk_gather_sum 1.071 |
1.63× | [1.62, 1.63] | 通过 |
cuda_n4096_d5_k13_consume |
uniform-random · all-pairs · hot · F5 | tiga.knn_build_consume_prepared_ttir 0.663 |
torch.cdist_topk_gather_sum 1.074 |
1.62× | [1.62, 1.63] | 通过 |
dense_matmul_calibration
稠密 matmul 校准门禁:编译器自动选择无 Torch 的 cuBLASLt 运行时路径,并对 torch.mm/cuBLAS 设门禁。
| 存档用例 | 测试条件 | 被测实现(ms) | 对标实现(ms) | 加速比 | 加速比的 95% 置信区间 | 性能检查 |
|---|---|---|---|---|---|---|
m2048_n2048_k2048_fp16 |
dense · contiguous · hot · F2048 | tiga.compiler_auto 0.192 |
torch.mm.cublas 0.193 |
1.00× | [1.00, 1.01] | 通过 |
dense_attention
写成 MessagePassing 的精确稠密 attention,经 Domain、Iter 与 Kernel IR lowering 为编译器生成的 TTIR(完整 Cartesian、causal 与 grouped-query 关系)。对标实现为 Flash SDPA(torch.sdpa.flash)。
| 存档用例 | 测试条件 | 被测实现(ms) | 对标实现(ms) | 加速比 | 加速比的 95% 置信区间 | 性能检查 |
|---|---|---|---|---|---|---|
b1_h16_n4096_d64_fp16 |
cartesian · dense · consumer-only · F64 | tiga.direct_ttir 0.772 |
torch.sdpa.flash 0.829 |
1.07× | [1.07, 1.08] | 通过 |
b1_h16_n4096_d64_fp16_causal |
lower-triangular · dense · consumer-only · F64 | tiga.direct_ttir 0.446 |
torch.sdpa.flash 0.498 |
1.12× | [1.10, 1.13] | 通过 |
b1_h16_n4096_d64_fp16_kvh4 |
cartesian · dense · consumer-only · F64 | tiga.direct_ttir 0.777 |
torch.sdpa.flash 0.842 |
1.08× | [1.08, 1.09] | 通过 |
horizontal_fusion
同一共享关系上兄弟消息传递 kernel 的横向融合。对标实现为匹配的手写融合 Triton oracle。
| 存档用例 | 测试条件 | 被测实现(ms) | 对标实现(ms) | 加速比 | 加速比的 95% 置信区间 | 性能检查 |
|---|---|---|---|---|---|---|
cuda_n131072_degree16_i64 |
regular · local · hot · F1 | tiga.compiler_fused 0.022 |
triton.fused_oracle 0.023 |
1.05× | [1.04, 1.06] | 通过 |
message_passing_backward
前向消息传递 UDF 的编译器推导 VJP,包括零安全的乘积 reducer VJP 与半径几何反向。对标实现为匹配的手写 Triton kernel 与 torch.autograd。
| 存档用例 | 测试条件 | 被测实现(ms) | 对标实现(ms) | 加速比 | 加速比的 95% 置信区间 | 性能检查 |
|---|---|---|---|---|---|---|
regular_random_cuda_i64_n131072_degree16_dx |
regular · random · hot · F1 | tiga.generated_vjp 0.058 |
handwritten.triton 0.059 |
1.01× | [1.01, 1.02] | 通过 |
regular_random_cuda_i64_n131072_degree16_dweight |
regular · random · hot · F1 | tiga.generated_vjp 0.016 |
handwritten.triton.saved 0.020 |
1.25× | [1.25, 1.26] | 通过 |
regular_random_cuda_i64_n131072_degree16_dweight_f16 |
regular · random · hot · F16 | tiga.generated_vjp 2.054 |
handwritten.triton.saved 2.060 |
1.00× | [1.00, 1.00] | 通过 |
regular_random_cuda_i64_n131072_degree16_dweight_f64 |
regular · random · hot · F64 | tiga.generated_vjp 2.304 |
handwritten.triton.saved 2.313 |
1.00× | [1.00, 1.00] | 通过 |
powerlaw_random_cuda_i64_n131072_degree16_dx |
powerlaw · random · hot · F1 | tiga.generated_vjp 0.057 |
handwritten.triton 0.059 |
1.03× | [1.03, 1.04] | 通过 |
powerlaw_random_cuda_i64_n131072_degree16_dweight_f16 |
powerlaw · random · hot · F16 | tiga.generated_vjp 1.996 |
handwritten.triton.saved 2.005 |
1.00× | [1.00, 1.01] | 通过 |
regular_edge_local_cuda_i64_n131072_degree16_product |
regular · edge-local · hot · F1 | tiga.generated_vjp 0.072 |
handwritten.triton 0.073 |
1.02× | [1.02, 1.03] | 通过 |
radius_fixed_snapshot_cuda_n32768_d3_degree32 |
radius-fixed-snapshot · cell-list · hot · F4 | tiga.generated_vjp 0.240 |
handwritten.triton 0.259 |
1.08× | [1.07, 1.08] | 通过 |
linear_attention
写成未归一化递推的因果线性 attention,融合为单个 scan TTIR kernel;秩四前缀状态从不物化。对标实现为官方 FLA 实现。
| 存档用例 | 测试条件 | 被测实现(ms) | 对标实现(ms) | 加速比 | 加速比的 95% 置信区间 | 性能检查 |
|---|---|---|---|---|---|---|
l64_t512_k16_v16_fp32 |
causal-prefix · dense-state · hot · F256 | tiga.compiler_scan_contract 0.106 |
fla.chunk 0.109 |
1.04× | [1.02, 1.05] | 通过 |
sparse_attention
带语义准入阈值的 tile 剪枝稀疏 attention,阈值穿过 reducer IR 进入通用稠密流式 lowering。对标实现为相同剪枝阈值下的官方 flash-sparse-attn kernel。
| 存档用例 | 测试条件 | 被测实现(ms) | 对标实现(ms) | 加速比 | 加速比的 95% 置信区间 | 性能检查 |
|---|---|---|---|---|---|---|
b1_h16_n4096_d64_fp16 |
dynamic-score-tile · dense · hot · F64 | tiga.compiler_tile_pruned 0.907 |
flash_sparse_attn.official 1.072 |
1.18× | [1.18, 1.19] | 通过 |
cpu_pointwise_fusion
CPU Tensor 逐点融合,lowering 为 512 位 LLVM 向量,运行在惰性创建的常驻 worker 池上。对标实现为 torch.compile/Inductor。
| 存档用例 | 测试条件 | 被测实现(ms) | 对标实现(ms) | 加速比 | 加速比的 95% 置信区间 | 性能检查 |
|---|---|---|---|---|---|---|
n4000000_f32_t16 |
contiguous · local · cold · F1 | tiga.llvm.vector_parallel 0.951 |
torch.compile.inductor 1.020 |
1.07× | [1.05, 1.12] | 通过 |
cpu_relation
CPU 融合关系循环:gather、UDF 与 CSR 归约在单个嵌套 16 线程 LLVM 循环内完成。对标实现为 scipy.csr_matvec 与 CPU 上的 torch.sparse.mm。
| 存档用例 | 测试条件 | 被测实现(ms) | 对标实现(ms) | 加速比 | 加速比的 95% 置信区间 | 性能检查 |
|---|---|---|---|---|---|---|
regular_permuted_i32_n131072_degree16_t16 |
regular · permuted · hot · F1 | tiga.llvm.parallel_relation 0.124 |
scipy.csr_matvec 0.781 |
6.32× | [5.54, 6.66] | 通过 |
pagerank
固定迭代 PageRank,捕获为单个 gf_control.repeat 递推,每轮迭代一个融合 TTIR kernel 加两个 ping-pong 缓冲区。对标实现为迭代次数完全相同的 torch.sparse.mm 递推。
| 存档用例 | 测试条件 | 被测实现(ms) | 对标实现(ms) | 加速比 | 加速比的 95% 置信区间 | 性能检查 |
|---|---|---|---|---|---|---|
cuda_fp32_iter20 |
regular-degree-16 · cyclic · hot · F1 · N262144 | tiga.control 0.590 |
torch.sparse.mm 1.379 |
2.34× | [2.31, 2.52] | 通过 |
cuda_fp32_iter20 |
regular-degree-16 · cyclic · hot · F1 · N65536 | tiga.control 0.190 |
torch.sparse.mm 0.352 |
1.85× | [1.82, 1.88] | 通过 |
cuda_fp32_iter20 |
regular-degree-32 · cyclic · hot · F1 · N262144 | tiga.control 2.462 |
torch.sparse.mm 2.583 |
1.05× | [1.04, 1.05] | 通过 |
cuda_fp32_iter20 |
regular-degree-32 · cyclic · hot · F1 · N65536 | tiga.control 0.244 |
torch.sparse.mm 0.380 |
1.56× | [1.54, 1.58] | 通过 |
cuda_fp32_iter20 |
regular-degree-4 · cyclic · hot · F1 · N262144 | tiga.control 0.217 |
torch.sparse.mm 0.357 |
1.64× | [1.61, 1.67] | 通过 |
cuda_fp32_iter20 |
regular-degree-4 · cyclic · hot · F1 · N65536 | tiga.control 0.190 |
torch.sparse.mm 0.354 |
1.86× | [1.83, 1.92] | 通过 |
visualization_heatmap
由普通 Tensor IR 组合的标量场 → RGB 热图准备。对标实现为 torch.compile/Inductor。
| 存档用例 | 测试条件 | 被测实现(ms) | 对标实现(ms) | 加速比 | 加速比的 95% 置信区间 | 性能检查 |
|---|---|---|---|---|---|---|
h2048_w2048_rgb_f32 |
image-grid · contiguous · consumer-only · F3 | tiga.tensor_ttir 0.100 |
torch.inductor.fused 0.115 |
1.15× | [1.14, 1.17] | 通过 |